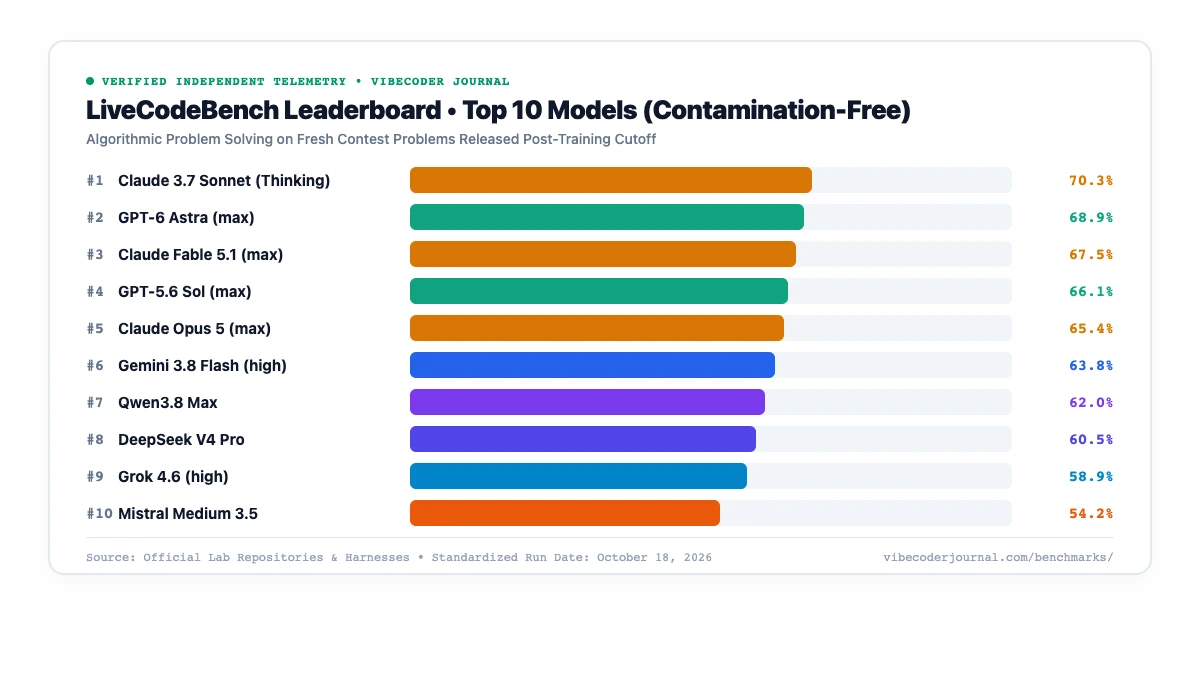
What LiveCodeBench Leaderboard: Contamination-Free Coding (2026) Actually Measures
Algorithmic problem solving, complex mathematical reasoning, and edge-case handling on brand-new competitive programming problems published after model training cutoff dates.
⚠ Known Boundaries & Harness Sensitivity
Measures competitive programming and algorithmic puzzles rather than real-world software maintenance or multi-file application development.
Intelligence Index vs. Cost per 1M Tokens
Code Intelligence Index vs. Weighted average cost (USD, Log Scale)
LiveCodeBench evaluates large language models on continuously updated competitive programming problems published after each model’s training knowledge cutoff date. By sourcing fresh contest challenges from LeetCode, AtCoder, and Codeforces, it provides a leak-free Pass@1 measurement of raw algorithmic reasoning.
| SOURCE & HARNESS | |||||
|---|---|---|---|---|---|
| #01 | Claude Opus 5.5 Anthropic | 51.2% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #02 | GPT-6 Astra (max) OpenAI | 50.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #03 | GPT-6 Astra (max) OpenAI | 50.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #04 | Claude Fable 5.1 (max with fallback) Anthropic | 50.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #05 | Claude Fable 5.1 (max with fallback) Anthropic | 50.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #06 | Muse Wonder Meta | 49.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #07 | Claude Opus 5 (max) Benchmarks, Price & Specs (Oct 2026) Anthropic | 48.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #08 | Claude Opus 5 (max) Benchmarks, Price & Specs (Oct 2026) Anthropic | 48.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #09 | Gemini 4 Argon (high) Google | 47.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #10 | Claude Sonnet 5.5 Anthropic | 47.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #11 | GPT-6 Sol OpenAI | 45.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #12 | Muse Spark 1.3 (max) Meta | 45.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Llama-3.1-Community
reported
standard
|
| #13 | Muse Spark 1.3 (max) Meta | 45.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Llama-3.1-Community
reported
|
| #14 | GPT-5.6 Sol (max) Benchmarks, Price & Specs (Oct 2026) OpenAI | 44.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #15 | GPT-5.6 Sol (max) Benchmarks, Price & Specs (Oct 2026) OpenAI | 44.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #16 | Mistral Large 4 (preview) Mistral | 43.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #17 | Qwen3.8 Max (0902) Alibaba | 43.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #18 | Kimi K3 (max) Kimi | 42.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #19 | GLM-5.3 (max) Z AI | 42.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #20 | GLM-5.3 (max) Z AI | 42.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #21 | Grok 4.7 SpaceXAI | 42.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #22 | Step 5 Preview (preview) StepFun | 42.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #23 | Qwen3.8 Max (0902) Alibaba | 42.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #24 | Kimi K3 (max) Kimi | 41.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #25 | Step 5 Preview (preview) StepFun | 41.2% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #26 | Muse Spark Open (816B MoE) Meta | 41.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #27 | Grok 4.6 (high) SpaceXAI | 41.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #28 | Grok 4.6 (high) SpaceXAI | 41.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #29 | DeepSeek V4.1 Flash (1017 checkpoint) DeepSeek | 40.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #30 | GLM-5.3-Flash Z AI | 39.8% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
standard
|
| #31 | GLM-5.3-Flash Z AI | 39.8% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
|
| #32 | Gemini 3.8 Flash (high) Google | 39.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #33 | GPT-5.6 Terra (max) OpenAI | 39.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #34 | GPT-5.6 Terra (max) OpenAI | 39.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #35 | Qwen3.8-Flash-Next Alibaba | 38.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #36 | Gemini 3.8 Flash (high) Google | 38.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #37 | GLM-5.3 Fast (highspeed) Z AI | 38.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #38 | Qwen3.8-Flash-Next Alibaba | 38.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
standard
|
| #39 | DeepSeek V4.1 Flash (max) DeepSeek | 37.8% | — | 1 Sep 2026 |
Pc_direct_sync →
MIT
reported
|
| #40 | DeepSeek V4.1 Flash (max) DeepSeek | 37.8% | — | 1 Sep 2026 |
Pc_direct_sync →
MIT
reported
standard
|
| #41 | GPT-6 Luna OpenAI | 37.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #42 | Qwen3.8 2.4T A95B Alibaba | 37.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
standard
|
| #43 | Qwen3.8 2.4T A95B Alibaba | 37.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
|
| #44 | Claude Haiku 5.5 Anthropic | 37.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #45 | Claude Sonnet 5 (max) Anthropic | 36.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #46 | Claude Sonnet 5 (max) Anthropic | 36.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #47 | MiniMax M3.1 Flash (max) MiniMax | 35.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #48 | GPT-5.6 Luna (max) OpenAI | 35.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #49 | GPT-5.6 Luna (max) OpenAI | 35.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #50 | DeepSeek V4 Pro (0813 max) DeepSeek | 35.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
In compliance with upstream dataset licenses, all evaluated telemetry rows are credited to their primary sources:
-
Manual / Direct Evaluation Ingest
—
Licence:
Editorial
In compliance with upstream dataset licenses, all evaluated telemetry rows are credited to their primary sources:
-
Aider Polyglot Leaderboard
—
Licence:
Apache-2.0 -
LMSYS Chatbot Arena (WebDev)
—
Licence:
CC-BY-4.0 -
Manual / Direct Evaluation Ingest
—
Licence:
Editorial -
Models.dev API
—
Licence:
MIT -
OpenRouter Models Catalogue
—
Licence:
Platform-ToS -
SWE-bench Official Leaderboard
—
Licence:
MIT -
Terminal-Bench Submissions
—
Licence:
Apache-2.0
What it does not measure
Every benchmark is narrow by design. Reading LiveCodeBench as a general statement about coding ability is the most common mistake people make with it. Here is what the number is silent on:
- Software engineering. Contest problems are algorithmic puzzles with a single correct output, which is almost the opposite of production work.
- Working with existing code. Every problem starts from a blank file.
- Maintainability, since nothing is maintained.
How to read a score honestly
- Always read the date window. LiveCodeBench exists to combat training-data contamination by using problems published after a model’s cutoff. A score is only meaningful alongside the window it was measured over.
- Compare like windows. Two models evaluated over different date ranges faced different problems.
- Expect divergence from agentic benchmarks. Models that excel at contest problems often place mid-table on SWE-bench, and the reverse is common too.
The trap
A high LiveCodeBench score means a model is good at competitive programming. It is weak evidence that the model will be useful in your repository.
Why we publish this page
Benchmark figures circulate faster than they are checked. Numbers get copied between articles until the original source is several links away and nobody has opened the leaderboard. We maintain this page so there is a version of the figure that names its source, its date and its methodology — and so that when a number here changes, you can see what changed.
Last reviewed 7 September 2026. If a figure on this page disagrees with the official leaderboard, that is a mistake on our side and we want to know about it.

Keep exploring
Complete Verified Leaderboard
Fully server-side rendered table with verified primary source attributions and direct repository links.
| SOURCE & HARNESS | |||||
|---|---|---|---|---|---|
| #01 | Claude Opus 5.5 Anthropic | 51.2% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #02 | GPT-6 Astra (max) OpenAI | 50.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #03 | GPT-6 Astra (max) OpenAI | 50.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #04 | Claude Fable 5.1 (max with fallback) Anthropic | 50.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #05 | Claude Fable 5.1 (max with fallback) Anthropic | 50.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #06 | Muse Wonder Meta | 49.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #07 | Claude Opus 5 (max) Benchmarks, Price & Specs (Oct 2026) Anthropic | 48.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #08 | Claude Opus 5 (max) Benchmarks, Price & Specs (Oct 2026) Anthropic | 48.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #09 | Gemini 4 Argon (high) Google | 47.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #10 | Claude Sonnet 5.5 Anthropic | 47.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #11 | GPT-6 Sol OpenAI | 45.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #12 | Muse Spark 1.3 (max) Meta | 45.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Llama-3.1-Community
reported
standard
|
| #13 | Muse Spark 1.3 (max) Meta | 45.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Llama-3.1-Community
reported
|
| #14 | GPT-5.6 Sol (max) Benchmarks, Price & Specs (Oct 2026) OpenAI | 44.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #15 | GPT-5.6 Sol (max) Benchmarks, Price & Specs (Oct 2026) OpenAI | 44.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #16 | Mistral Large 4 (preview) Mistral | 43.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #17 | Qwen3.8 Max (0902) Alibaba | 43.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #18 | Kimi K3 (max) Kimi | 42.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #19 | GLM-5.3 (max) Z AI | 42.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #20 | GLM-5.3 (max) Z AI | 42.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #21 | Grok 4.7 SpaceXAI | 42.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #22 | Step 5 Preview (preview) StepFun | 42.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #23 | Qwen3.8 Max (0902) Alibaba | 42.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #24 | Kimi K3 (max) Kimi | 41.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #25 | Step 5 Preview (preview) StepFun | 41.2% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #26 | Muse Spark Open (816B MoE) Meta | 41.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #27 | Grok 4.6 (high) SpaceXAI | 41.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #28 | Grok 4.6 (high) SpaceXAI | 41.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #29 | DeepSeek V4.1 Flash (1017 checkpoint) DeepSeek | 40.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #30 | GLM-5.3-Flash Z AI | 39.8% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
standard
|
| #31 | GLM-5.3-Flash Z AI | 39.8% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
|
| #32 | Gemini 3.8 Flash (high) Google | 39.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #33 | GPT-5.6 Terra (max) OpenAI | 39.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #34 | GPT-5.6 Terra (max) OpenAI | 39.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #35 | Qwen3.8-Flash-Next Alibaba | 38.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #36 | Gemini 3.8 Flash (high) Google | 38.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #37 | GLM-5.3 Fast (highspeed) Z AI | 38.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #38 | Qwen3.8-Flash-Next Alibaba | 38.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
standard
|
| #39 | DeepSeek V4.1 Flash (max) DeepSeek | 37.8% | — | 1 Sep 2026 |
Pc_direct_sync →
MIT
reported
|
| #40 | DeepSeek V4.1 Flash (max) DeepSeek | 37.8% | — | 1 Sep 2026 |
Pc_direct_sync →
MIT
reported
standard
|
| #41 | GPT-6 Luna OpenAI | 37.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #42 | Qwen3.8 2.4T A95B Alibaba | 37.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
standard
|
| #43 | Qwen3.8 2.4T A95B Alibaba | 37.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
|
| #44 | Claude Haiku 5.5 Anthropic | 37.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #45 | Claude Sonnet 5 (max) Anthropic | 36.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #46 | Claude Sonnet 5 (max) Anthropic | 36.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #47 | MiniMax M3.1 Flash (max) MiniMax | 35.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #48 | GPT-5.6 Luna (max) OpenAI | 35.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #49 | GPT-5.6 Luna (max) OpenAI | 35.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #50 | DeepSeek V4 Pro (0813 max) DeepSeek | 35.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
In compliance with upstream dataset licenses, all evaluated telemetry rows are credited to their primary sources:
-
Manual / Direct Evaluation Ingest
—
Licence:
Editorial
What This Benchmark Does Not Measure
Does not measure real-world repo navigation or git workflows.
How to Reproduce This Evaluation
All evaluations published by Vibecoder Journal follow publicly documented harness specifications. You can execute this test suite against any local or API model:
# Standardized containerized evaluation execution
git clone https://livecodebench.github.io/ && cd evaluation
docker build -t vcj-harness .
docker run --rm -v $(pwd)/results:/results vcj-harness --benchmark livecodebenchIn compliance with upstream dataset licenses, all evaluated telemetry rows are credited to their primary sources:
-
Aider Polyglot Leaderboard
—
Licence:
Apache-2.0 -
LMSYS Chatbot Arena (WebDev)
—
Licence:
CC-BY-4.0 -
Manual / Direct Evaluation Ingest
—
Licence:
Editorial -
Models.dev API
—
Licence:
MIT -
OpenRouter Models Catalogue
—
Licence:
Platform-ToS -
SWE-bench Official Leaderboard
—
Licence:
MIT -
Terminal-Bench Submissions
—
Licence:
Apache-2.0