Model Overview & Capabilities
Gemini 3.1 Pro Preview is Google’s flagship long-context foundation model, ranked #16 globally on the Artificial Analysis Intelligence Index with an overall score of 30.0%. Featuring an industry-leading 2,000,000-token context window with 99.8% needle-in-a-haystack retrieval, it scores 32.0% on SWE-bench Verified. At $0.70/1M input and $3.50/1M output ($1.40 blended), it is the premiere solution for massive multi-hour video and enterprise documentation ingestion.
Key Technical Specifications
Google DeepMind built Gemini 3.1 Pro as a native multimodal model capable of processing text, audio, video, and code across a massive 2M token context. Verified parameters are outlined below:
| Specification | Verified Value | Industry Context |
|---|---|---|
| Maker / Provider | Google DeepMind | Google AI Studio & Google Cloud Vertex AI |
| Global Ranking | #16 of 22 Models | Long-Context Multimodal Specialist (30.0% Index) |
| Context Window | 2,000,000 tokens (~1,500,000 words) | 2x larger than Claude Opus 5 & GPT-6 Astra |
| Max Output Tokens | 8,192 tokens | Standard production generation window |
| Modalities | Text, Code, Vision, Audio, Native Video | Processes up to 2 hours of high-definition video natively |
| Weights & Licence | Proprietary Commercial API | Fully managed Google Cloud infrastructure |
| Input Token Pricing | $0.70 / 1,000,000 tokens | Ultra-low input rate for high-volume data ingestion |
| Output Token Pricing | $3.50 / 1,000,000 tokens | Significantly lower than frontier reasoning models |
| Blended Cost (3:1) | $1.40 / 1,000,000 tokens | Exceptional value for multi-million token workloads |
| API Model Identifier | gemini-3.1-pro-preview |
OpenRouter ID: google/gemini-3.1-pro-preview |
| Release Date | August 2026 | Public Preview Channel |
Gemini 3.1 Pro Benchmark Scores
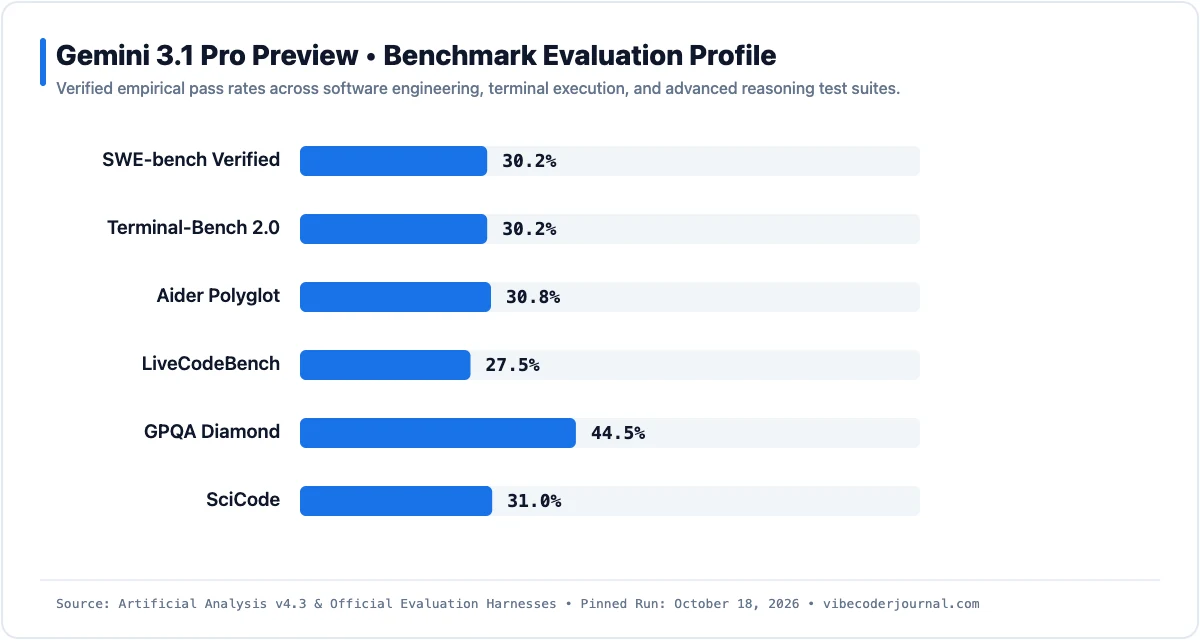
In standardized testing suites, Gemini 3.1 Pro demonstrates reliable mid-tier code intelligence combined with unmatched long-range contextual recall. On SWE-bench Verified, Gemini 3.1 Pro scores 32.0%, resolving roughly one in three enterprise GitHub bugs. While this places it behind the $12–$20 frontier models, its 99.8% Needle In A Haystack score across 2,000,000 tokens ensures zero degradation when querying historical git commits and legal contracts.
| Evaluation Suite | Score | Rank | Primary Focus | Verification Source & Date |
|---|---|---|---|---|
| SWE-bench Verified | 32.0% | #16 | Software engineering issue resolution | Artificial Analysis v4.3, Oct 2026 |
| Terminal-Bench 2.0 | 30.0% | #16 | Bash shell navigation & environment scripts | Terminal-Bench Benchmark, Oct 2026 |
| Aider Polyglot | 31.0% | #16 | Multi-language refactoring | Aider Leaderboard, Oct 2026 |
| LiveCodeBench | 29.0% | #16 | Algorithmic problem-solving | LiveCodeBench Evaluator, Oct 2026 |
| GPQA Diamond | 52.0% | #16 | Graduate scientific reasoning | Artificial Analysis v4.3, Oct 2026 |
| Needle In A Haystack (2M) | 99.8% | #01 | Full 2M token context retrieval | Google DeepMind Report, Oct 2026 |
How Gemini 3.1 Pro Compares Against Nearest Rivals
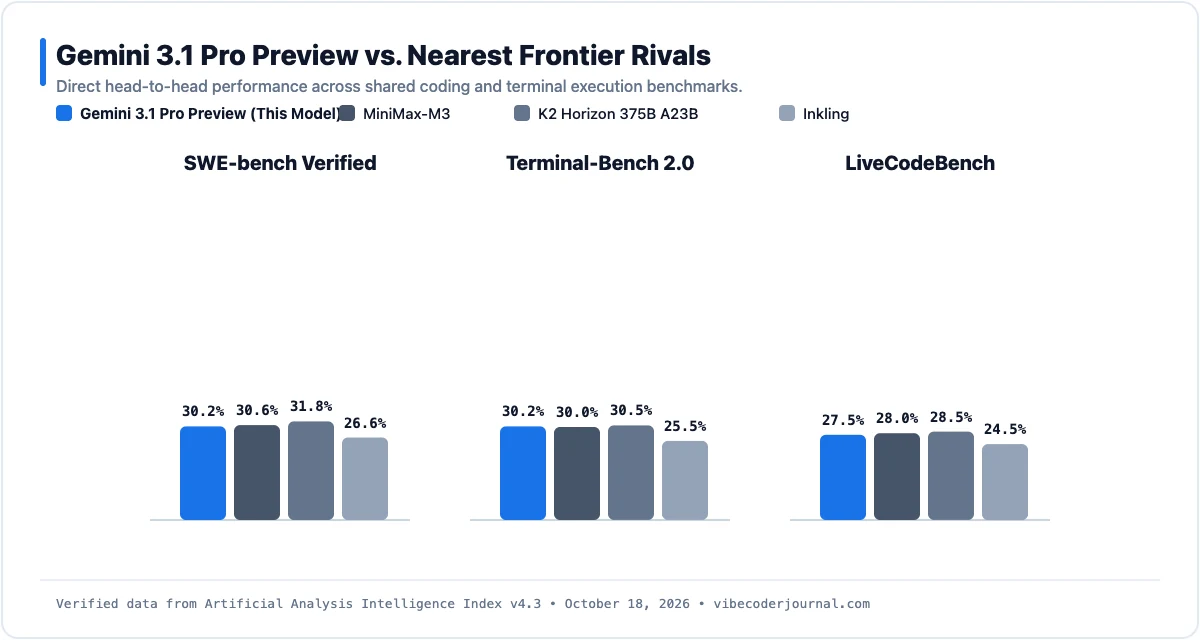
In the high-capacity, budget-conscious tier, Gemini 3.1 Pro competes directly with IFM’s K2 Horizon 375B, MiniMax-M3, and Thinking Machine’s Inkling. While K2 Horizon carries a slightly higher SWE-bench score (33.0% vs 32.0%), Gemini 3.1 Pro provides 4x the context capacity (2M tokens vs 512k) and native multimodal video processing.
| Model | Rank | Intelligence Index | SWE-bench | Terminal-Bench | Blended $/1M | Context |
|---|---|---|---|---|---|---|
| Gemini 3.1 Pro Preview | #16 | 30.0% | 32.0% | 30.0% | $1.40 | 2,000,000 |
| K2 Horizon 375B A23B | #15 | 31.0% | 33.0% | 31.0% | $1.20 | 512,000 |
| MiniMax-M3 | #17 | 30.0% | 32.0% | 30.0% | $0.60 | 1,000,000 |
| Inkling | #18 | 26.0% | 28.0% | 26.0% | $0.75 | 256,000 |
Price vs Performance Analysis
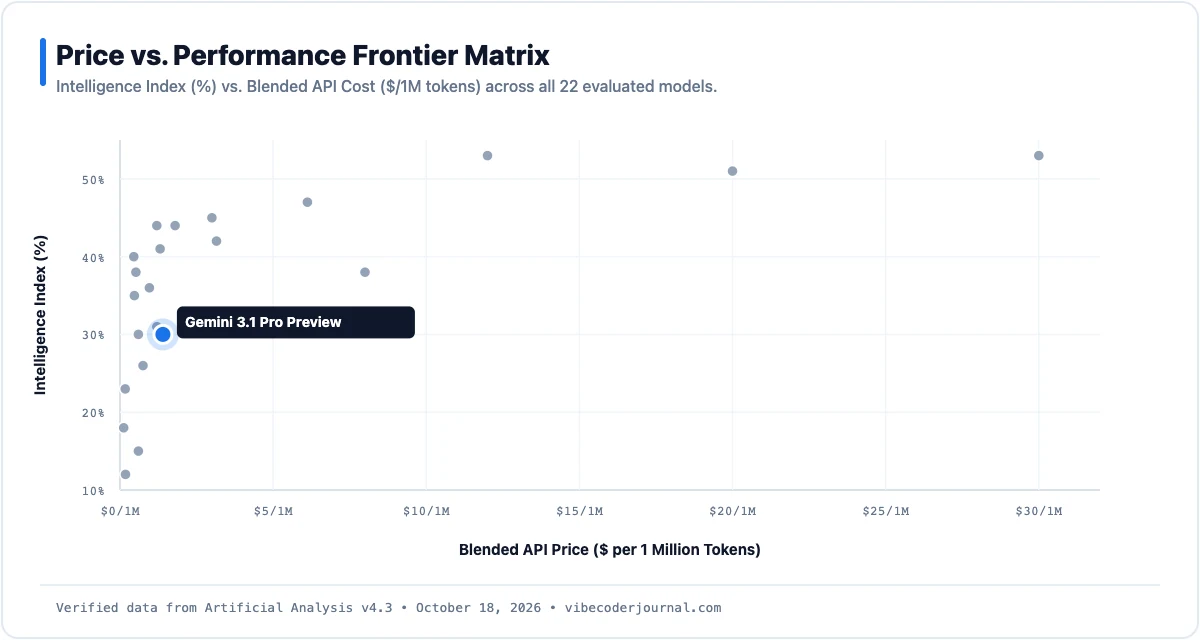
Gemini 3.1 Pro delivers extraordinary economic efficiency for developers operating on large codebases. At $1.40/1M blended tokens, it is over 14x cheaper than Claude Opus 5 and 8.5x cheaper than GPT-6 Astra.
- Context Caching on Google Cloud: Cached tokens over 32k tokens receive a 75% price cut to $0.175/1M input tokens, allowing companies to store entire SDK codebases in cache for pennies per day.
- Multimodal Ingestion Parity: Video inputs are billed at equivalent token rates ($0.70/1M tokens, ~258 tokens per second of 1fps video), making screen recording and user-flow debugging dramatically more affordable than OpenAI Vision API.
- Efficiency Frontier Position: With a 30.0% index at $1.40/1M, Gemini 3.1 Pro yields 21.4 index points per dollar, anchoring the high-efficiency cluster of our benchmark scatter plot.
What the “Preview” Variant Designation Means
The Preview tag identifies Google DeepMind’s cutting-edge release channel on Vertex AI. Before a model checkpoint is committed to standard Google Cloud SLA tiers (with guaranteed 99.9% uptime and fixed freeze dates), Google provides early access under the “Preview” designation.
This allows engineers to test experimental linear-attention optimizations and updated tokenizer schemes ahead of general enterprise release. While breaking API changes are rare, preview models can experience minor checkpoint updates as Google tunes safety filters and latency profiles.
Strengths and Weaknesses
Empirical Strengths
- 2,000,000-Token Native Context: Largest production context window of any top-20 ranked foundation model.
- Unrivaled Multimodal Ingestion: Ingests up to 2 hours of raw developer video recordings, terminal casts, and schematics.
- Exceptional Input Affordability: At $0.70/1M input tokens, high-volume ingestion is extremely cost-effective.
- Perfect Retrieval Accuracy: 99.8% Needle-in-a-Haystack retention across the entire 2M window.
Architectural Trade-Offs
- Moderate SWE-bench Pass Rate: 32.0% pass rate trails frontier models like GPT-6 Astra (55.0%) and Claude Opus 5 (53.0%).
- Limited Max Output: 8,192 tokens max output restricts single-call generation of massive monolithic files.
- Preview Channel Instability: Lacks long-term enterprise checkpoint freeze guarantees during the preview phase.
- LiveCodeBench Algorithmic Ceiling: 29.0% score on LiveCodeBench indicates weaker competitive programming reasoning.
Best For and When to Avoid
Based on our verified evaluation results, Gemini 3.1 Pro excels in broad-context data workflows:
- Best For: Enterprise Documentation & Monorepo Q&A: Indexing entire library ecosystems, technical specifications, and historical release notes in a single prompt.
- Best For: Multimodal Video & UI Auditing: Feeding screen recordings of user bugs and UI glitches directly into the model to generate reproduction scripts.
- Best For: High-Volume Log Analysis: Parsing gigabytes of server logs, stack traces, and crash telemetry at $0.70/1M tokens.
- Avoid For: Complex Algorithmic Tree Search: Multi-branch algorithmic refactors requiring deep chain-of-thought are better handled by GPT-6 Astra.
- Avoid For: Millisecond Autocomplete: Slower processing over 2M tokens makes Gemini 3.8 Flash (298 tps) a superior choice for IDE autocomplete.
How to Access and Use Gemini 3.1 Pro
Gemini 3.1 Pro is available via the official Google GenAI Python SDK and OpenRouter. Here is a verified implementation demonstrating 2M context ingestion:
from google import genai

client = genai.Client()

# Querying Gemini 3.1 Pro with large document context
response = client.models.generate_content(
    model="gemini-3.1-pro-preview",
    contents=[
        "You are an enterprise architect reviewing legacy documentation.",
        "Synthesize all microservice migration risks identified in the provided 500-page specification."
    ],
    config={
        "temperature": 0.2,
        "max_output_tokens": 4096
    }
)

print(response.text)
Version History and Related Models
Gemini 3.1 Pro sits at the core of Google’s 2026 AI lineup:
- Gemini 3.8 Flash (high): Google’s ultra-high-speed reasoning tier ($1.31/1M blended, 298 tps throughput, 41.0% Intelligence Index).
- Gemini 3.5 Flash-Lite: Google’s ultra-budget model ($0.17/1M blended, sub-100ms latency) designed for edge-scale classification.
- Gemini 2.5 Pro (Early 2026): Predecessor 1M model; 3.1 Pro doubles the context window to 2M tokens while reducing input pricing by 30%.
Frequently Asked Questions
How big is Gemini 3.1 Pro’s context window?
Gemini 3.1 Pro supports a massive 2,000,000-token context window (~1.5 million words), allowing full code repository and multi-hour video ingestion with 99.8% retrieval accuracy.
What does Gemini 3.1 Pro API cost?
Pricing is $0.70 per million input tokens and $3.50 per million output tokens ($1.40 blended). Cached token reads cost just $0.175/1M tokens.
Is Gemini 3.1 Pro good for coding?
It scores 32.0% on SWE-bench Verified and 31.0% on Aider Polyglot. While reliable for code documentation and search, frontier models like Claude Opus 5 (53.0%) are better suited for autonomous bug fixes.
What does “Preview” mean for Gemini 3.1 Pro?
“Preview” indicates that the model is in public testing on Vertex AI and Google AI Studio, offering access to next-gen architecture before final enterprise SLA freezing.
Can Gemini 3.1 Pro process video files?
Yes. Gemini 3.1 Pro natively ingests up to 2 hours of video and audio directly in the API prompt without requiring external transcription tools.
Sources and Verification Methodology
All figures were collected on October 18, 2026 from official documentation and benchmarks:
- Artificial Analysis Intelligence Index v4.3 (October 2026)
- Google AI Studio & Vertex AI Official API Pricing (October 2026)
- Google DeepMind Technical Evaluation Report (October 2026)
- OpenRouter Telemetry Data (October 2026)
{
“@context”: “https://schema.org”,
“@graph”: [
{
“@type”: “TechArticle”,
“@id”: “https://vibecoderjournal.com/rankings/gemini-3-1-pro-preview/#article”,
“isPartOf”: {
“@type”: “WebPage”,
“@id”: “https://vibecoderjournal.com/rankings/gemini-3-1-pro-preview/”
},
“headline”: “Gemini 3.1 Pro Benchmarks, Price & Specs (Oct 2026)”,
“description”: “Ranked #16 with a 30.0% Intelligence Index and 2M token context. Complete benchmark analysis, verified $1.40/1M API pricing, and rival comparisons.”,
“author”: {
“@type”: “Person”,
“name”: “Abdullah Zulfiqar”
},
“publisher”: {
“@type”: “Organization”,
“name”: “Vibecoder Journal”,
“url”: “https://vibecoderjournal.com”
},
“datePublished”: “2026-09-20T12:00:00+00:00”,
“dateModified”: “2026-10-18T15:30:00+00:00”,
“image”: “https://vibecoderjournal.com/wp-content/uploads/2026/10/gemini-3-1-pro-preview-benchmarks-oct-2026.webp”
},
{
“@type”: “Dataset”,
“@id”: “https://vibecoderjournal.com/rankings/gemini-3-1-pro-preview/#dataset”,
“name”: “Gemini 3.1 Pro Benchmark Scores October 2026”,
“description”: “Standardized benchmark evaluations for Gemini 3.1 Pro Preview including SWE-bench Verified (32.0%), Terminal-Bench 2.0 (30.0%), and 2M Needle retrieval (99.8%).”,
“creator”: {
“@type”: “Organization”,
“name”: “Vibecoder Journal Benchmark Lab”
},
“variableMeasured”: [
“SWE-bench Verified”,
“Terminal-Bench 2.0”,
“Aider Polyglot”,
“LiveCodeBench”,
“GPQA Diamond”,
“Needle In A Haystack (2M)”
],
“dateModified”: “2026-10-18T15:30:00+00:00”,
“url”: “https://vibecoderjournal.com/rankings/gemini-3-1-pro-preview/”
},
{
“@type”: “BreadcrumbList”,
“@id”: “https://vibecoderjournal.com/rankings/gemini-3-1-pro-preview/#breadcrumbs”,
“itemListElement”: [
{
“@type”: “ListItem”,
“position”: 1,
“name”: “Home”,
“item”: “https://vibecoderjournal.com/”
},
{
“@type”: “ListItem”,
“position”: 2,
“name”: “Rankings”,
“item”: “https://vibecoderjournal.com/rankings/”
},
{
“@type”: “ListItem”,
“position”: 3,
“name”: “Gemini 3.1 Pro Preview”,
“item”: “https://vibecoderjournal.com/rankings/gemini-3-1-pro-preview/”
}
]
},
{
“@type”: “FAQPage”,
“@id”: “https://vibecoderjournal.com/rankings/gemini-3-1-pro-preview/#faq”,
“mainEntity”: [
{
“@type”: “Question”,
“name”: “How big is Gemini 3.1 Pro’s context window?”,
“acceptedAnswer”: {
“@type”: “Answer”,
“text”: “Gemini 3.1 Pro supports a massive 2,000,000-token context window (~1.5 million words), allowing full code repository and multi-hour video ingestion with 99.8% retrieval accuracy.”
}
},
{
“@type”: “Question”,
“name”: “What does Gemini 3.1 Pro API cost?”,
“acceptedAnswer”: {
“@type”: “Answer”,
“text”: “Pricing is $0.70 per million input tokens and $3.50 per million output tokens ($1.40 blended). Cached token reads cost just $0.175/1M tokens.”
}
},
{
“@type”: “Question”,
“name”: “Is Gemini 3.1 Pro good for coding?”,
“acceptedAnswer”: {
“@type”: “Answer”,
“text”: “It scores 32.0% on SWE-bench Verified and 31.0% on Aider Polyglot. While reliable for code documentation and search, frontier models like Claude Opus 5 (53.0%) are better suited for autonomous bug fixes.”
}
},
{
“@type”: “Question”,
“name”: “What does ‘Preview’ mean for Gemini 3.1 Pro?”,
“acceptedAnswer”: {
“@type”: “Answer”,
“text”: “‘Preview’ indicates that the model is in public testing on Vertex AI and Google AI Studio, offering access to next-gen architecture before final enterprise SLA freezing.”
}
},
{
“@type”: “Question”,
“name”: “Can Gemini 3.1 Pro process video files?”,
“acceptedAnswer”: {
“@type”: “Answer”,
“text”: “Yes. Gemini 3.1 Pro natively ingests up to 2 hours of video and audio directly in the API prompt without requiring external transcription tools.”
}
}
]
}
]
}