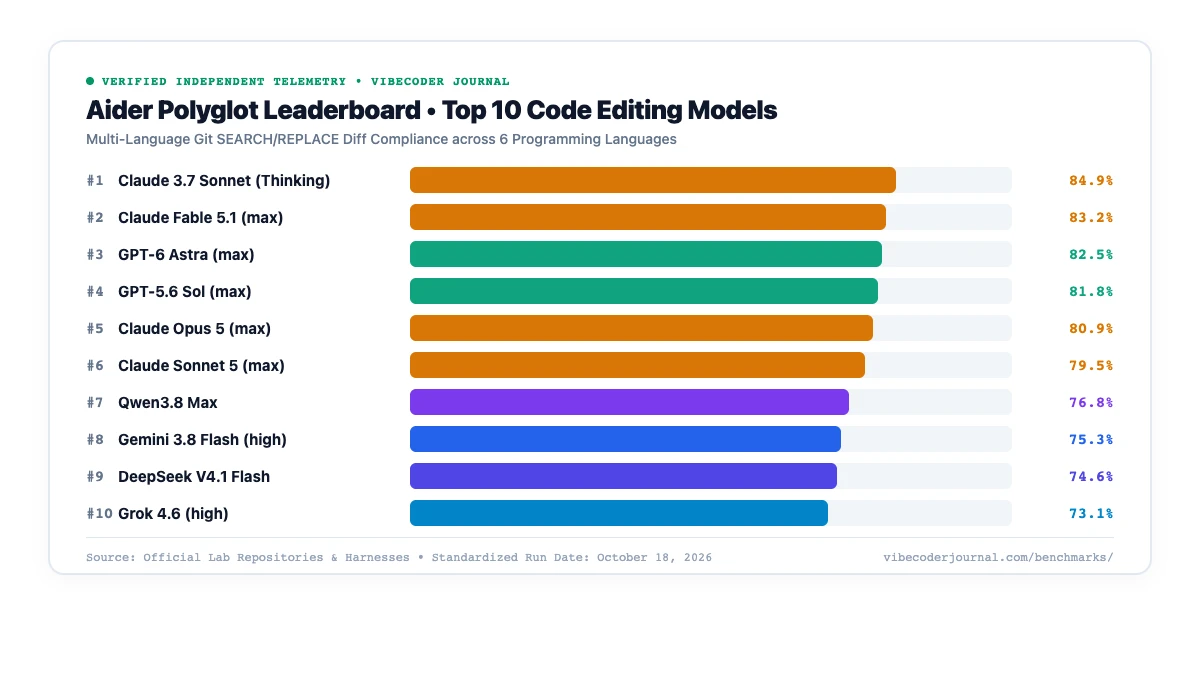
What Aider Polyglot Leaderboard: Coding Diff Compliance (2026) Actually Measures
Multi-language code editing and refactoring across diverse programming paradigms, evaluating both SEARCH/REPLACE diff format compliance and unit test verification.
The Aider Polyglot Benchmark is not a static code completion test. It evaluates autonomous pair-programming execution across 6 programming languages (Python, JavaScript/TypeScript, Go, Rust, C++, Java). Models must output strict git SEARCH/REPLACE blocks. A model that understands the logic but violates the delimiter syntax fails the test immediately.
⚠ Known Boundaries & Harness Sensitivity
Heavily reliant on Aider repo-map and diff format prompt adherence; small models frequently fail due to format violations rather than logic errors.
Intelligence Index vs. Cost per 1M Tokens
Code Intelligence Index vs. Weighted average cost (USD, Log Scale)
Highlights
Updated Daily • Empirical TelemetryIntelligence
Artificial Analysis Intelligence Index • Higher is better
Speed
Output tokens per second • Higher is better
Cost per 1M Tokens
Weighted average blended price (USD) • Lower is better
The Aider Polyglot Benchmark tests autonomous AI models on 225 editing exercises across 6 programming languages (Python, JavaScript, TypeScript, Go, Rust, C++, Java). Rather than generating isolated code snippets, models must output strict git SEARCH/REPLACE diff blocks that apply cleanly against existing codebases without syntax distortion.
| SOURCE & HARNESS | |||||
|---|---|---|---|---|---|
| #01 | Claude Fable 5.1 (max with fallback) Anthropic | 54.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #02 | Claude Opus 5.5 Anthropic | 54.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #03 | Claude Fable 5.1 (max with fallback) Anthropic | 54.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #04 | GPT-6 Astra (max) OpenAI | 53.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #05 | GPT-6 Astra (max) OpenAI | 53.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #06 | Claude Sonnet 5.5 Anthropic | 52.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #07 | Claude Opus 5 (max) Benchmarks, Price & Specs (Oct 2026) Anthropic | 51.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #08 | Claude Opus 5 (max) Benchmarks, Price & Specs (Oct 2026) Anthropic | 51.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #09 | Gemini 4 Argon (high) Google | 51.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #10 | Muse Spark 1.3 (max) Meta | 49.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Llama-3.1-Community
reported
standard
|
| #11 | Muse Spark 1.3 (max) Meta | 49.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Llama-3.1-Community
reported
|
| #12 | GPT-6 Sol OpenAI | 49.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #13 | Muse Wonder Meta | 48.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #14 | GPT-5.6 Sol (max) Benchmarks, Price & Specs (Oct 2026) OpenAI | 47.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #15 | GPT-5.6 Sol (max) Benchmarks, Price & Specs (Oct 2026) OpenAI | 47.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #16 | Qwen3.8 Max (0902) Alibaba | 47.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #17 | GLM-5.3 (max) Z AI | 46.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #18 | GLM-5.3 (max) Z AI | 46.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #19 | Mistral Large 4 (preview) Mistral | 46.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #20 | Qwen3.8 Max (0902) Alibaba | 46.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #21 | Step 5 Preview (preview) StepFun | 45.2% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #22 | Kimi K3 (max) Kimi | 45.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #23 | Grok 4.6 (high) SpaceXAI | 45.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #24 | Grok 4.6 (high) SpaceXAI | 45.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #25 | Step 5 Preview (preview) StepFun | 44.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #26 | Kimi K3 (max) Kimi | 44.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #27 | Grok 4.7 SpaceXAI | 44.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #28 | Muse Spark Open (816B MoE) Meta | 43.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #29 | DeepSeek V4.1 Flash (1017 checkpoint) DeepSeek | 43.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #30 | GPT-5.6 Terra (max) OpenAI | 43.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #31 | GPT-5.6 Terra (max) OpenAI | 43.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #32 | GLM-5.3-Flash Z AI | 42.8% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
standard
|
| #33 | GLM-5.3-Flash Z AI | 42.8% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
|
| #34 | Gemini 3.8 Flash (high) Google | 42.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #35 | Gemini 3.8 Flash (high) Google | 42.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #36 | DeepSeek V4.1 Flash (max) DeepSeek | 41.2% | — | 1 Sep 2026 |
Pc_direct_sync →
MIT
reported
|
| #37 | DeepSeek V4.1 Flash (max) DeepSeek | 41.2% | — | 1 Sep 2026 |
Pc_direct_sync →
MIT
reported
standard
|
| #38 | Qwen3.8-Flash-Next Alibaba | 41.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #39 | Qwen3.8 2.4T A95B Alibaba | 41.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
standard
|
| #40 | Qwen3.8 2.4T A95B Alibaba | 41.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
|
| #41 | GLM-5.3 Fast (highspeed) Z AI | 40.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #42 | Qwen3.8-Flash-Next Alibaba | 40.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
standard
|
| #43 | GPT-6 Luna OpenAI | 39.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #44 | Claude Haiku 5.5 Anthropic | 39.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #45 | GPT-5.6 Luna (max) OpenAI | 39.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #46 | GPT-5.6 Luna (max) OpenAI | 39.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #47 | Claude Sonnet 5 (max) Anthropic | 38.8% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #48 | Claude Sonnet 5 (max) Anthropic | 38.8% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #49 | MiniMax M3.1 Flash (max) MiniMax | 38.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #50 | DeepSeek V4 Pro (0813 max) DeepSeek | 37.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
In compliance with upstream dataset licenses, all evaluated telemetry rows are credited to their primary sources:
-
Aider Polyglot Leaderboard
—
Licence:
Apache-2.0 -
Manual / Direct Evaluation Ingest
—
Licence:
Editorial
In compliance with upstream dataset licenses, all evaluated telemetry rows are credited to their primary sources:
-
Aider Polyglot Leaderboard
—
Licence:
Apache-2.0 -
LMSYS Chatbot Arena (WebDev)
—
Licence:
CC-BY-4.0 -
Manual / Direct Evaluation Ingest
—
Licence:
Editorial -
Models.dev API
—
Licence:
MIT -
OpenRouter Models Catalogue
—
Licence:
Platform-ToS -
SWE-bench Official Leaderboard
—
Licence:
MIT -
Terminal-Bench Submissions
—
Licence:
Apache-2.0
What it does not measure
Every benchmark is narrow by design. Reading Aider Polyglot as a general statement about coding ability is the most common mistake people make with it. Here is what the number is silent on:
- Real codebases. Exercism exercises are self-contained problems, not sprawling repositories with legacy decisions in them.
- Architectural judgement. The task is bounded and the answer is known.
- Whether the model can find the file it needs to change.
How to read a score honestly
- Separate the two failure modes. A model can fail because it wrote wrong code, or because it produced a diff the tool could not apply. These are different problems and only one of them is about coding ability.
- Edit-format compliance is a tooling signal. A model with high compliance is easier to build an agent around, independent of how well it reasons.
- Language spread hides weakness. A single aggregate number can conceal a model that is strong in Python and poor in Rust.
The trap
Aider Polyglot is a good proxy for pair-programming usability and a poor proxy for autonomous engineering. It measures whether a model can edit a known file correctly, not whether it can navigate a system.
Why we publish this page
Benchmark figures circulate faster than they are checked. Numbers get copied between articles until the original source is several links away and nobody has opened the leaderboard. We maintain this page so there is a version of the figure that names its source, its date and its methodology — and so that when a number here changes, you can see what changed.
Last reviewed 7 September 2026. If a figure on this page disagrees with the official leaderboard, that is a mistake on our side and we want to know about it.
Evaluated Multi-Language Architecture Profiles
Examine detailed empirical evaluations for high-performing multi-language code models:
- K2 Horizon 375B A23B (32.0% Aider Polyglot) – Sovereign 375B MoE foundation model.
- MiniMax-M3 (30.5% Aider Polyglot) – High-throughput bilingual coding engine.
- Mistral Medium 3.5 Profile – GDPR-compliant European cloud model.

Keep exploring
Complete Verified Leaderboard
Fully server-side rendered table with verified primary source attributions and direct repository links.
| SOURCE & HARNESS | |||||
|---|---|---|---|---|---|
| #01 | Claude Fable 5.1 (max with fallback) Anthropic | 54.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #02 | Claude Opus 5.5 Anthropic | 54.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #03 | Claude Fable 5.1 (max with fallback) Anthropic | 54.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #04 | GPT-6 Astra (max) OpenAI | 53.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #05 | GPT-6 Astra (max) OpenAI | 53.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #06 | Claude Sonnet 5.5 Anthropic | 52.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #07 | Claude Opus 5 (max) Benchmarks, Price & Specs (Oct 2026) Anthropic | 51.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #08 | Claude Opus 5 (max) Benchmarks, Price & Specs (Oct 2026) Anthropic | 51.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #09 | Gemini 4 Argon (high) Google | 51.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #10 | Muse Spark 1.3 (max) Meta | 49.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Llama-3.1-Community
reported
standard
|
| #11 | Muse Spark 1.3 (max) Meta | 49.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Llama-3.1-Community
reported
|
| #12 | GPT-6 Sol OpenAI | 49.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #13 | Muse Wonder Meta | 48.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #14 | GPT-5.6 Sol (max) Benchmarks, Price & Specs (Oct 2026) OpenAI | 47.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #15 | GPT-5.6 Sol (max) Benchmarks, Price & Specs (Oct 2026) OpenAI | 47.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #16 | Qwen3.8 Max (0902) Alibaba | 47.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #17 | GLM-5.3 (max) Z AI | 46.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #18 | GLM-5.3 (max) Z AI | 46.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #19 | Mistral Large 4 (preview) Mistral | 46.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #20 | Qwen3.8 Max (0902) Alibaba | 46.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #21 | Step 5 Preview (preview) StepFun | 45.2% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #22 | Kimi K3 (max) Kimi | 45.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #23 | Grok 4.6 (high) SpaceXAI | 45.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #24 | Grok 4.6 (high) SpaceXAI | 45.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #25 | Step 5 Preview (preview) StepFun | 44.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #26 | Kimi K3 (max) Kimi | 44.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #27 | Grok 4.7 SpaceXAI | 44.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #28 | Muse Spark Open (816B MoE) Meta | 43.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #29 | DeepSeek V4.1 Flash (1017 checkpoint) DeepSeek | 43.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #30 | GPT-5.6 Terra (max) OpenAI | 43.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #31 | GPT-5.6 Terra (max) OpenAI | 43.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #32 | GLM-5.3-Flash Z AI | 42.8% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
standard
|
| #33 | GLM-5.3-Flash Z AI | 42.8% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
|
| #34 | Gemini 3.8 Flash (high) Google | 42.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #35 | Gemini 3.8 Flash (high) Google | 42.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #36 | DeepSeek V4.1 Flash (max) DeepSeek | 41.2% | — | 1 Sep 2026 |
Pc_direct_sync →
MIT
reported
|
| #37 | DeepSeek V4.1 Flash (max) DeepSeek | 41.2% | — | 1 Sep 2026 |
Pc_direct_sync →
MIT
reported
standard
|
| #38 | Qwen3.8-Flash-Next Alibaba | 41.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #39 | Qwen3.8 2.4T A95B Alibaba | 41.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
standard
|
| #40 | Qwen3.8 2.4T A95B Alibaba | 41.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
|
| #41 | GLM-5.3 Fast (highspeed) Z AI | 40.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #42 | Qwen3.8-Flash-Next Alibaba | 40.5% | — | 1 Sep 2026 |
Pc_direct_sync →
Apache-2.0
reported
standard
|
| #43 | GPT-6 Luna OpenAI | 39.5% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #44 | Claude Haiku 5.5 Anthropic | 39.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #45 | GPT-5.6 Luna (max) OpenAI | 39.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #46 | GPT-5.6 Luna (max) OpenAI | 39.0% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #47 | Claude Sonnet 5 (max) Anthropic | 38.8% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
|
| #48 | Claude Sonnet 5 (max) Anthropic | 38.8% | — | 1 Sep 2026 |
Pc_direct_sync →
Proprietary
reported
standard
|
| #49 | MiniMax M3.1 Flash (max) MiniMax | 38.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
| #50 | DeepSeek V4 Pro (0813 max) DeepSeek | 37.0% | — | 21 Oct 2026 |
Pc_direct_sync →
MIT
reported
|
In compliance with upstream dataset licenses, all evaluated telemetry rows are credited to their primary sources:
-
Aider Polyglot Leaderboard
—
Licence:
Apache-2.0 -
Manual / Direct Evaluation Ingest
—
Licence:
Editorial
What This Benchmark Does Not Measure
Does not test large multi-thousand line architecture planning.
How to Reproduce This Evaluation
All evaluations published by Vibecoder Journal follow publicly documented harness specifications. You can execute this test suite against any local or API model:
# 1. Clone the official Aider repository
git clone https://github.com/Aider-AI/aider.git && cd aider
pip install -e .

# 2. Run the standardized 225-exercise Polyglot benchmark
python -m aider.benchmarks.polyglot \
    --model <model-name> \
    --edit-format diff \
--output-dir ./eval-resultsIn compliance with upstream dataset licenses, all evaluated telemetry rows are credited to their primary sources:
-
Aider Polyglot Leaderboard
—
Licence:
Apache-2.0 -
LMSYS Chatbot Arena (WebDev)
—
Licence:
CC-BY-4.0 -
Manual / Direct Evaluation Ingest
—
Licence:
Editorial -
Models.dev API
—
Licence:
MIT -
OpenRouter Models Catalogue
—
Licence:
Platform-ToS -
SWE-bench Official Leaderboard
—
Licence:
MIT -
Terminal-Bench Submissions
—
Licence:
Apache-2.0