GLM-5.2 vs Qwen 3.6: which is better? For hard coding and agent work, GLM-5.2 wins clearly. On the tests both labs report, it scores 62.1 vs 53.5 on SWE-bench Pro and 48.9 vs 36.2 on NL2Repo against Qwen3.6-27B. That’s not a fair fight on size, though. GLM-5.2 is a 744B-parameter model, while Qwen 3.6’s open models are 27B and 35B. That makes Qwen 3.6 about 4 to 12 times cheaper per job, and it runs on a single 24GB GPU or a Mac. Below: the benchmarks, real API costs, local hardware, and which one to pick.
Verdict: Use GLM-5.2 when you want the strongest open coding model and you’ll call it through an API. It’s near the top closed models on several coding tests. Use Qwen 3.6 when cost, speed, image input or running locally matter more. Qwen3.6-27B is one of the best coding models you can run on your own machine.
How to read these numbers: each lab’s benchmarks are self-reported on its official Hugging Face model card, and we didn’t re-run them. The GLM-5.2 and Qwen 3.6 cards don’t compare against each other, so in the comparison tables each model’s score comes from its own card, with its own test setup. Treat small gaps as noise and big gaps as real. Prices are Z.ai’s official list price for GLM-5.2 and OpenRouter’s lowest listed price for Qwen 3.6, checked 27 October 2026.
| GLM-5.2 | Qwen 3.6 | |
|---|---|---|
| Maker | Z.ai (Zhipu AI) | Alibaba (Qwen team) |
| Released | 16 June 2026 | April 2026 (Plus 2 Apr, open 27B and 35B-A3B mid to late April) |
| Open models | One size: ~744B total, 40B active (MoE) | 27B (dense) and 35B-A3B (MoE, 3B active) |
| API-only versions | None | Qwen3.6-Plus, Qwen3.6-Max-Preview |
| Context | 1M tokens | 262K native (up to ~1M with YaRN); Plus: 1M |
| Input types | Text only | Text, image, video |
| License | MIT | Apache 2.0 |
| API price (in / out per 1M) | $1.40 / $4.40 (Z.ai) | from $0.20 / $2.00 (27B), $0.05 / $0.70 (35B-A3B) |
GLM-5.2 vs Qwen 3.6 at a glance
These two come from China’s two most active open-model labs, but they’re built for different jobs.
GLM-5.2 is Z.ai’s flagship, released on 16 June 2026. It’s a very large Mixture-of-Experts model. Unsloth lists it at 744B total with 40B active per token, and Hugging Face shows about 753B in the weights. It has a 1-million-token context and multiple thinking effort levels. Z.ai’s pitch is long-horizon coding: its card reports strong results on hard, multi-hour software tasks like FrontierSWE and SWE-Marathon.
Qwen 3.6 is a family Alibaba released in April 2026. The open models are Qwen3.6-27B, a dense model, and Qwen3.6-35B-A3B, a small MoE with about 3B active parameters. Alibaba also sells API-only versions, Qwen3.6-Plus and Qwen3.6-Max-Preview. Every Qwen 3.6 open model reads images and video. GLM-5.2 is text only.
Both labs have released newer models since. GLM-5.2’s own Hugging Face page points to GLM-5.3, and its benchmark table compares against Qwen3.7-Max. Our model rankings track the latest versions. GLM-5.2 and Qwen 3.6 are still very popular, especially Qwen 3.6 for local use.
Coding benchmarks
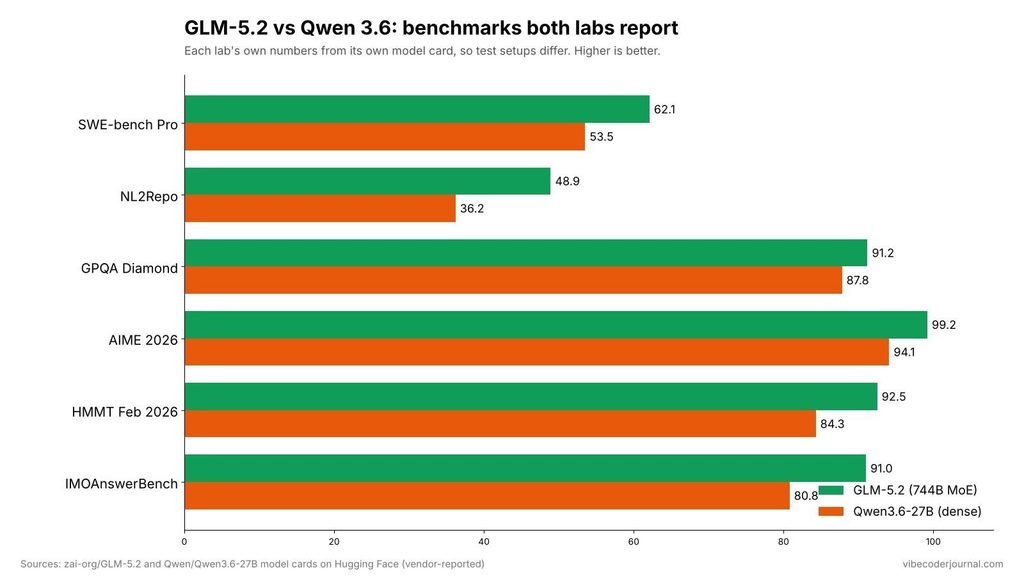
| Benchmark | GLM-5.2 | Qwen3.6-27B | Qwen3.6-35B-A3B |
|---|---|---|---|
| SWE-bench Pro | 62.1 | 53.5 | 49.5 |
| NL2Repo (build a repo from a spec) | 48.9 | 36.2 | 29.4 |
| SWE-bench Verified | not reported | 77.2 | 73.4 |
| Terminal-Bench | 81.0 (v2.1, Terminus-2) | 59.3 (v2.0) | 51.5 (v2.0) |
GLM-5.2 is the stronger coder. On SWE-bench Pro, the harder successor to SWE-bench Verified, it scores 62.1 against Qwen3.6-27B’s 53.5. On NL2Repo, where the model builds a whole repository from a description, it leads by almost 13 points.
Z.ai’s card also puts GLM-5.2 near the best closed models on some coding tests: – SWE-bench Pro 62.1, vs 58.6 for GPT-5.5 and 69.2 for Claude Opus 4.8 – FrontierSWE 74.4, vs 75.1 for Claude Opus 4.8 and 72.6 for GPT-5.5
Those are Z.ai’s own numbers.
Be careful with Terminal-Bench. GLM-5.2 reports version 2.1 and Qwen 3.6 reports version 2.0, so you can’t compare the numbers directly.
For a 27B model, Qwen3.6-27B is remarkable. Its 77.2 on SWE-bench Verified is close to the much larger Qwen3.5-397B (76.2 on the same card). On Terminal-Bench 2.0 it ties Claude 4.5 Opus at 59.3, according to Alibaba.
Agent and tool-use benchmarks
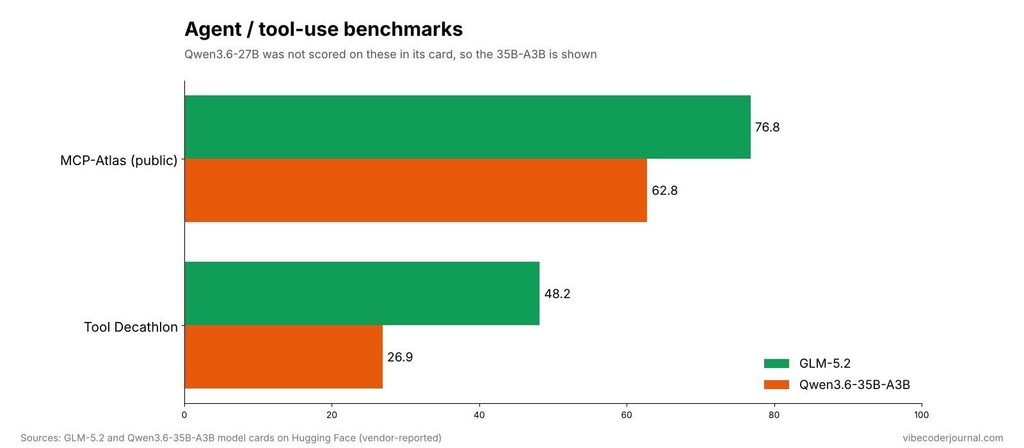
| Benchmark | GLM-5.2 | Qwen3.6-35B-A3B |
|---|---|---|
| MCP-Atlas (public set) | 76.8 | 62.8 |
| Tool Decathlon | 48.2 | 26.9 |
GLM-5.2 is much better at long, multi-tool agent tasks. On MCP-Atlas, which tests working with real MCP tool servers, it scores 76.8, close to Claude Opus 4.8’s 77.8 on Z.ai’s card. The small Qwen3.6-35B-A3B is far behind here, which is what you’d expect from a model with 3B active parameters.
Reasoning and math
| Benchmark | GLM-5.2 | Qwen3.6-27B |
|---|---|---|
| GPQA Diamond | 91.2 | 87.8 |
| AIME 2026 | 99.2 | 94.1 |
| HMMT Feb 2026 | 92.5 | 84.3 |
| IMOAnswerBench | 91.0 | 80.8 |
GLM-5.2 leads every shared reasoning test, by 3 to 10 points. Both cards also report Humanity’s Last Exam (HLE): GLM-5.2 40.5 and Qwen3.6-27B 24.0. Z.ai says its non-starred HLE results use the text-only subset, so we’ve left HLE out of the comparison.
Price: Qwen 3.6 is far cheaper
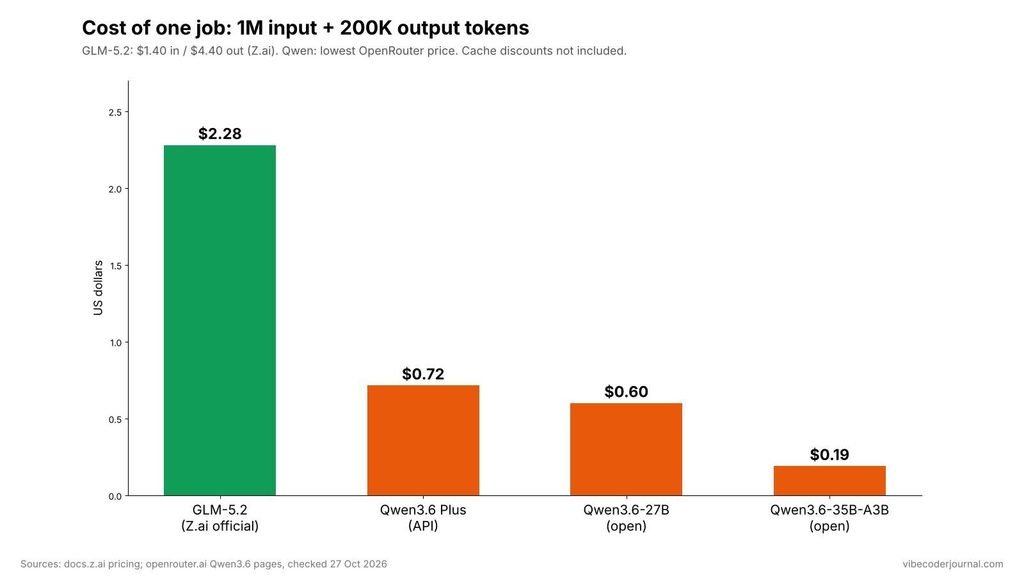
| Price per 1M tokens | Input | Output | Cost of 1M in + 200K out |
|---|---|---|---|
| GLM-5.2 (Z.ai official) | $1.40 | $4.40 | $2.28 |
| Qwen3.6-Plus (Alibaba, via OpenRouter) | $0.325 | $1.95 | $0.72 |
| Qwen3.6-27B (lowest OpenRouter provider) | $0.20 | $2.00 | $0.60 |
| Qwen3.6-35B-A3B (OpenRouter listed rate) | $0.05 | $0.70 | $0.19 |
GLM-5.2 costs roughly 3 to 4 times as much as Qwen3.6-Plus or Qwen3.6-27B per job, and about 12 times as much as Qwen3.6-35B-A3B. Z.ai lists cached input at $0.26 per 1M tokens, which brings GLM’s cost down a lot in long agent sessions that keep re-reading the same files. GLM-5.2 is also on 25 providers on OpenRouter, so shop around. Prices change often, so check before you commit.
For budget options, see our best free OpenRouter models tracker.
Running locally: Qwen 3.6 wins easily
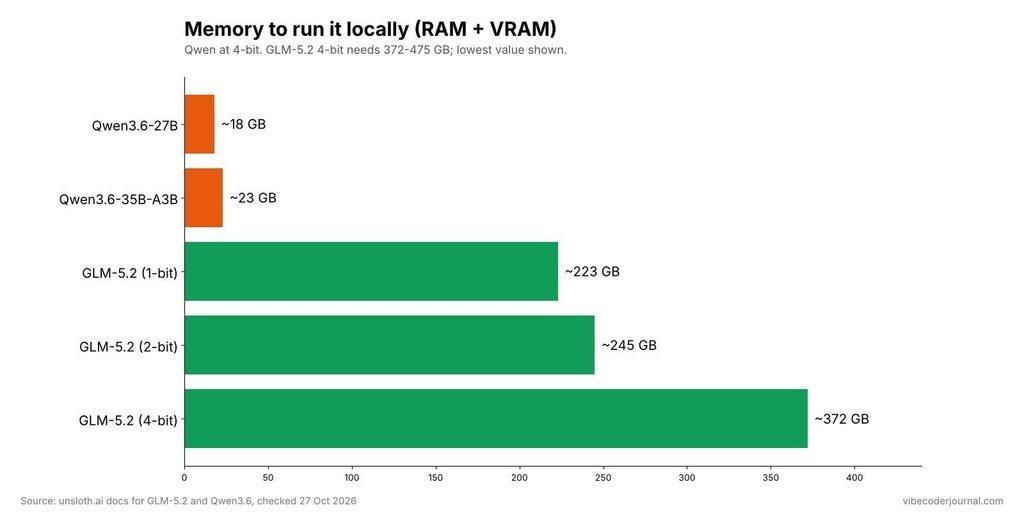
| Model | Memory needed (RAM + VRAM) |
|---|---|
| Qwen3.6-27B, 4-bit | ~18GB |
| Qwen3.6-35B-A3B, 4-bit | ~23GB |
| GLM-5.2, 1-bit | ~223GB |
| GLM-5.2, 2-bit | ~245GB |
| GLM-5.2, 4-bit | 372–475GB |
| GLM-5.2, full precision | ~1.5TB |
Qwen 3.6 runs on a single 24GB GPU or a 32GB Mac at 4-bit. Unsloth reports about 140–160 tokens/s for the 27B and 220–240 tokens/s for the 35B-A3B on an RTX 6000 with speculative decoding (MTP) switched on. That’s fast enough for interactive coding.
GLM-5.2 is a server-class model. Unsloth says the 2-bit quant fits a 256GB unified-memory Mac, or a single 24GB GPU with 256GB of system RAM using MoE offloading. Most people should use it through an API.
See our what fits in 32GB, run LLMs locally and local coding models benchmark pages for setup help.
Frequently asked questions
Is GLM-5.2 better than Qwen 3.6?
For coding and agent tasks, yes. On the tests both labs report, GLM-5.2 leads Qwen3.6-27B on SWE-bench Pro (62.1 vs 53.5), NL2Repo (48.9 vs 36.2) and every shared reasoning test. But GLM-5.2 is about 27 times larger. Qwen 3.6 is much cheaper and runs locally, so it’s the better value for everyday work.
Which is better for coding, GLM-5.2 or Qwen 3.6?
GLM-5.2. Z.ai reports 62.1 on SWE-bench Pro and 74.4 on FrontierSWE, close to top closed models. Qwen3.6-27B is the better choice if you want a coder that runs on a single 24GB GPU, scoring 77.2 on SWE-bench Verified according to Alibaba.
How much does GLM-5.2 cost compared to Qwen 3.6?
Z.ai lists GLM-5.2 at $1.40 input and $4.40 output per million tokens, with cached input at $0.26. On OpenRouter on 27 October 2026, Qwen3.6-27B started at $0.20 / $2.00, Qwen3.6-35B-A3B at $0.05 / $0.70, and Qwen3.6-Plus at $0.325 / $1.95.
Can I run GLM-5.2 locally?
Only on very large hardware. Unsloth says GLM-5.2 needs about 223GB at 1-bit, 245GB at 2-bit and 372 to 475GB at 4-bit. The 2-bit version fits a 256GB unified-memory Mac. Qwen3.6-27B needs only about 18GB at 4-bit.
Does GLM-5.2 support images?
No. GLM-5.2’s model card lists text generation only. Qwen 3.6’s open models (27B and 35B-A3B) accept image and video input, so pick Qwen for screenshots, mockups or scanned documents.
What is the context window of GLM-5.2 and Qwen 3.6?
GLM-5.2 supports 1 million tokens. Qwen3.6-27B and 35B-A3B support 262,144 tokens natively and up to about 1,010,000 with YaRN scaling. Qwen3.6-Plus is listed with a 1M context on OpenRouter.
Are GLM-5.2 and Qwen 3.6 open source?
GLM-5.2 is open-weight under the MIT license. Qwen3.6-27B and Qwen3.6-35B-A3B are open-weight under Apache 2.0. Qwen3.6-Plus and Qwen3.6-Max-Preview are API-only.
Sources
Checked 27 October 2026:
- GLM-5.2 model card (Z.ai), Hugging Face: https://huggingface.co/zai-org/GLM-5.2
- Z.ai API pricing: https://docs.z.ai/guides/overview/pricing
- Qwen3.6 GitHub repository: https://github.com/QwenLM/Qwen3.6
- Qwen3.6-27B model card: https://huggingface.co/Qwen/Qwen3.6-27B
- Qwen3.6-35B-A3B model card: https://huggingface.co/Qwen/Qwen3.6-35B-A3B
- OpenRouter, GLM 5.2: https://openrouter.ai/z-ai/glm-5.2

Keep exploring