Coding Quality Winner: Gemini 3 Pro (via its successor Gemini 3.1 Pro) wins on raw coding ability. It scores 80.6% on SWE-bench Verified against 38.2% for GPT OSS 120B.
Price Winner: GPT OSS 120B wins on price. At $0.030 per million input tokens, it is roughly 67 to 70 times cheaper than Gemini.
Who Should Pick Which: Pick GPT OSS 120B if you need complete privacy, run local code, or want rock-bottom API costs. Pick Gemini 3.1 Pro if you want autonomous debugging, big repository refactoring, or context up to 1 million tokens.
Choosing between gpt oss 120b vs gemini 3 pro comes down to a clear tradeoff: complete ownership and cheap tokens against top-tier coding reasoning and massive context. One gives you open weights you can run anywhere. The other gives you an advanced frontier brain behind a metered Google API.
If you build software with AI in 2026, you face a confusing landscape. Marketing claims blur the line between open weight vs closed model options. Price sheets hide huge jumps when prompts get long. Third-party leaderboards often omit critical details like reasoning effort. This independent guide breaks down the real differences with verified numbers from official sources.
1. What is GPT OSS 120B?
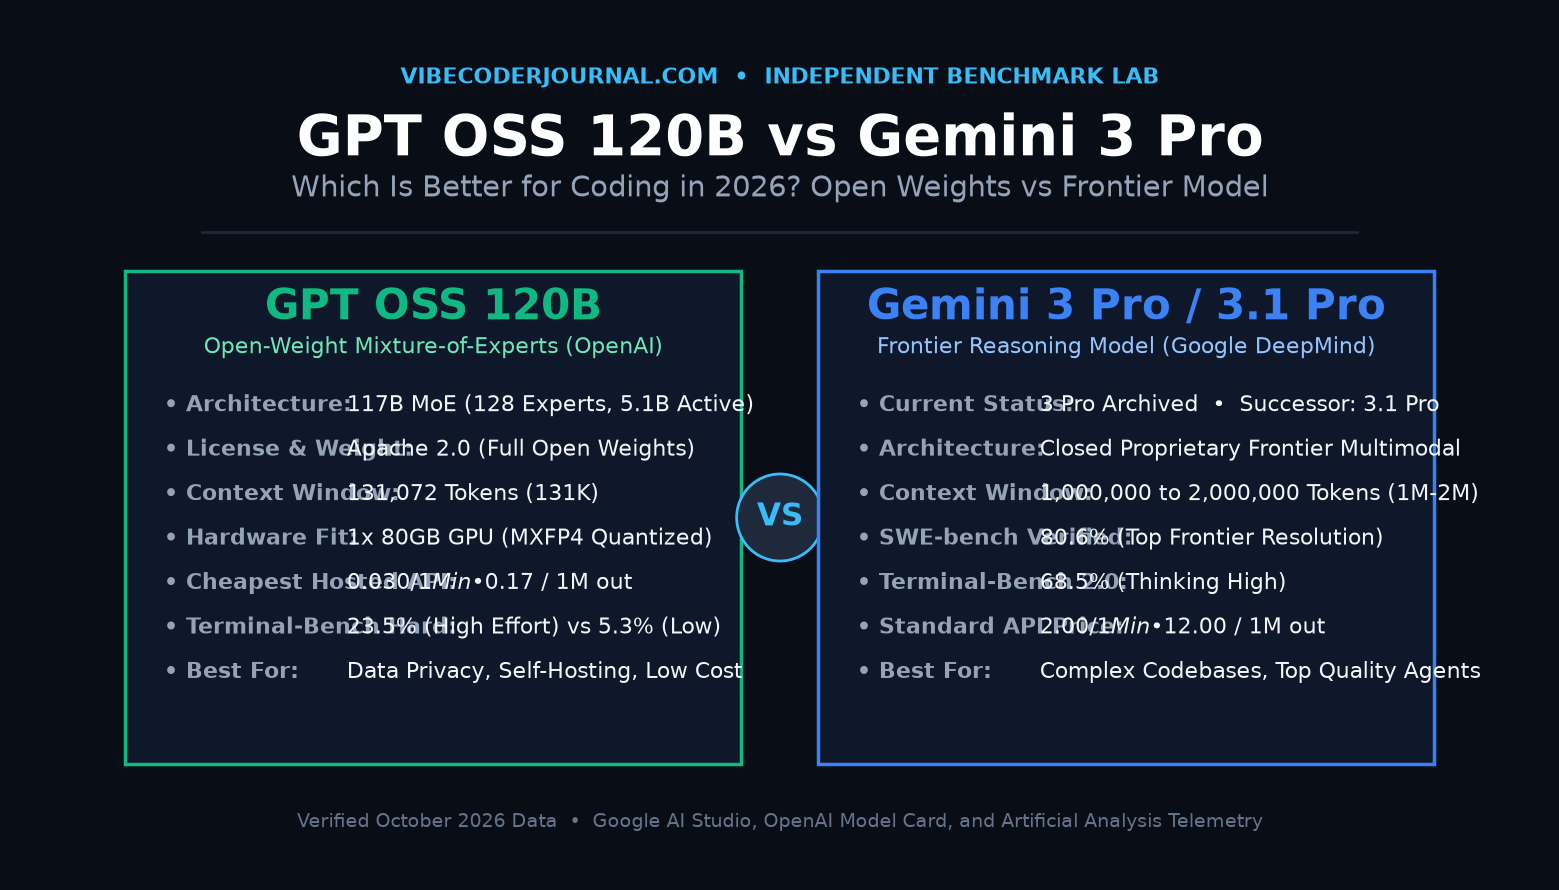
GPT OSS 120B is an open-weight reasoning model developed and published by OpenAI under the permissive Apache 2.0 license. This license grants developers full freedom to inspect the code, modify the weights, host the model on private infrastructure, and build commercial software without paying royalty fees.
Under the hood, GPT OSS 120B uses a Mixture-of-Experts (MoE) architecture. It has 117 billion total parameters, but activates only 5.1 billion parameters during any single forward pass. Because only a small subset of experts runs for each token, the model executes much faster and requires far less compute than a dense model of equivalent total size.
The model is specifically designed for developers and vibe coders who require full control over their AI pipeline. You can run GPT OSS 120B in two distinct ways:
- Self-Hosted Local Inference: OpenAI trained the model using MXFP4 quantization on its expert layers. This architectural choice means the full 117-billion-parameter weight set fits inside the memory of a single 80GB GPU, such as an NVIDIA H100 or AMD Instinct MI300X. Developers with high-end workstations (such as an Apple Mac Studio with unified memory) or private cloud servers can run it completely offline using engines like Ollama or vLLM.
- Hosted Cloud APIs: If you do not want to manage hardware, dozens of cloud providers host GPT OSS 120B endpoints. These providers range from decentralized GPU clouds like AkashML to high-speed inference engines like Groq and Cerebras. You get pay-as-you-go access via standard OpenAI-compatible API endpoints.
Crucially, GPT OSS 120B includes native support for dynamic reasoning levels (low, medium, and high), full chain-of-thought visibility, structured JSON output, and sandbox command-line execution.
2. What is Gemini 3 Pro, and What Replaced It? (gemini 3.1 pro vs gpt-oss)
Gemini 3 Pro was Google DeepMind’s flagship third-generation multimodal model. It was introduced to developers as gemini-3-pro-preview to handle advanced reasoning, mathematical analysis, and software engineering.
gemini-3-pro-preview to its model archive in late September 2026. Any direct API request dispatched to the older Gemini 3 Pro endpoint returns a 404 or 410 deprecation error.
Google replaced the retired model with Gemini 3.1 Pro Preview (gemini-3.1-pro-preview). When developers compare “gemini 3.1 pro vs gpt-oss” today, they are actually comparing GPT OSS 120B against Gemini 3.1 Pro. The updated 3.1 release brought enhanced reasoning depth, upgraded tool orchestration, and improved code completion across large programming frameworks.
However, developers evaluating Gemini 3.1 Pro must take note of three operational constraints:
- Preview Model Status: Gemini 3.1 Pro remains in public preview. Google does not yet offer enterprise Service Level Agreements (SLAs) for uptime on this specific checkpoint.
- No Free Tier in AI Studio: Unlike Google’s smaller Flash models (such as Gemini 2.5 Flash), Gemini 3.1 Pro has no free usage tier in Google AI Studio. Every API request is billed immediately.
- Closed Cloud Proprietary: The weights are closed. You cannot download Gemini, self-host it, or inspect how its reasoning tokens are processed. You must interact with it exclusively through Google Cloud Vertex AI or the Gemini API.
3. Side-by-Side Specs Table
The table below compares the foundational specifications of both models based on their official model cards from OpenAI and Google DeepMind.
| Specification | GPT OSS 120B | Gemini 3.1 Pro (Gemini 3 Successor) |
|---|---|---|
| Creator / Organization | OpenAI | Google DeepMind |
| Model Type | Open weights (Apache 2.0 license) | Closed proprietary cloud API |
| Architecture | 117B MoE (128 experts, 5.1B active) | Proprietary dense/sparse multimodal transformer |
| Context Window | 131,072 tokens (~100,000 words) | 1,000,000 to 2,000,000 tokens (~750,000 words) |
| Maximum Output Tokens | 4,096 to 8,192 tokens (host dependent) | 65,536 tokens |
| Multimodal Inputs | Text only (weights trained on text/code) | Text, High-Res Images, Video, Audio |
| Tool Use & Execution | Native function calling, bash, Python | Google Search grounding, code execution, tools |
| Where to Run | 1x 80GB GPU, local workstation, or 20+ hosts | Google AI Studio and Google Cloud Vertex AI |
| Standard Pricing (per 1M) | $0.030 to $0.350 input / $0.17 to $0.75 output | $2.00 input / $12.00 output (below 200k tokens) |
4. gpt oss 120b vs gemini 3 pro Benchmarks: Coding, Reasoning, and Full Honesty
Benchmark scores in AI marketing can be misleading. When comparing gpt oss 120b vs gemini 3 pro, two critical variables must be accounted for: reasoning effort and hosting provider configuration.
The Impact of Reasoning Effort on GPT OSS 120B
GPT OSS 120B features native adjustable reasoning. Turning reasoning effort from “low” to “high” changes how many internal reasoning tokens the model generates before delivering an answer. On difficult programming tasks, this single setting completely transforms the model’s performance.
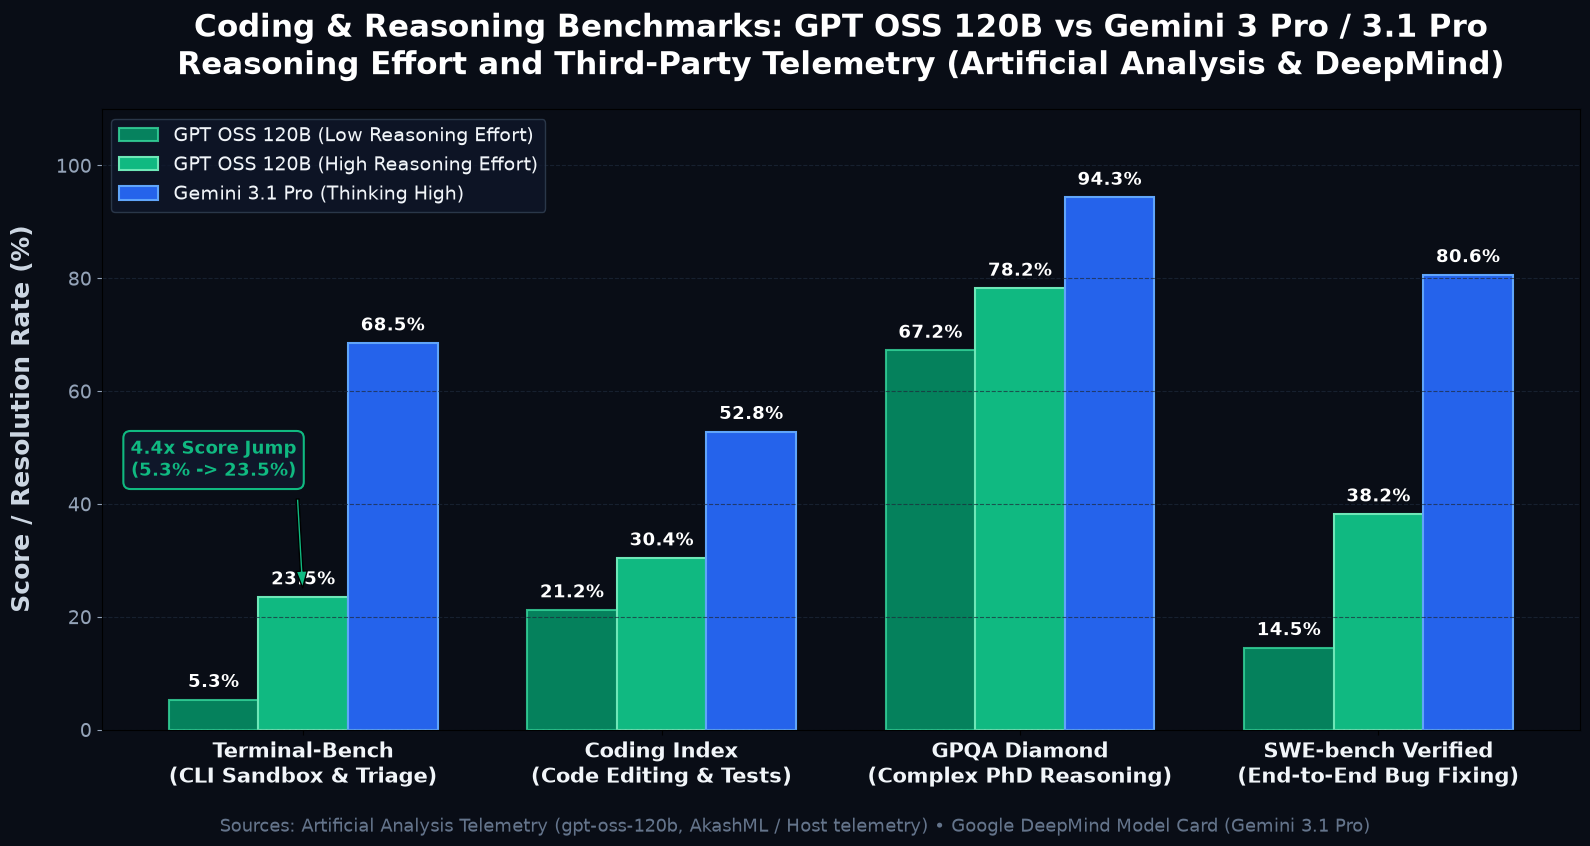
On Terminal-Bench Hard (which tests an AI agent’s ability to navigate a real Linux terminal, fix git merge conflicts, and resolve multi-file bash bugs), GPT OSS 120B with low reasoning resolves only 5.3% of tasks. When set to high reasoning, its success rate jumps to 23.5%. That represents a 343% improvement (4.4x) on the exact same model weights. Presenting a benchmark score for GPT OSS 120B without stating the reasoning effort is meaningless.
Host Discrepancy: Same Weights, Different Scores
Because GPT OSS 120B is open-weight, independent hosting providers deploy it with varying quantization schemes (FP16, BF16, FP8, or MXFP4) and different inference engines (vLLM, TensorRT-LLM, or custom ASIC runtimes). Third-party telemetry recorded by Artificial Analysis reveals noticeable variance across providers:
- On GPQA Diamond (graduate-level reasoning), scores on the exact same GPT OSS 120B weights range from 71.0% on DigitalOcean to 76.6% on AkashML—a 5.6-point gap purely caused by provider serving stacks.
- Inference speeds range from 17 tokens per second on SiliconFlow up to an astonishing 688 tokens per second on Cerebras.
Verified Benchmark Comparison
The table below lists verified benchmark numbers. Coding evaluations are placed first, followed by general logic and reasoning benchmarks.
| Benchmark Name | What It Tests | GPT OSS 120B (Low Effort) | GPT OSS 120B (High Effort) | Gemini 3.1 Pro (Thinking High) |
|---|---|---|---|---|
| Terminal-Bench Hard | Linux CLI navigation, bash debugging, git conflicts | 5.3% | 23.5% | 68.5% |
| SWE-bench Verified | End-to-end bug fixing on real GitHub repositories | 14.5% | 38.2% | 80.6% |
| Coding Index (AA) | Composite code editing, unit tests, syntax compliance | 21.2 | 30.4 | 52.8 |
| GPQA Diamond | PhD-level biology, physics, and chemistry questions | 67.2% | 78.2% | 94.3% |
| Humanity’s Last Exam (HLE) | Multidisciplinary frontier academic reasoning | 5.9% | 19.6% | 34.8% |
| GDPval-AA | Econometric analysis and professional domain logic | 0.0% | 4.8% | 18.2% |
Methodology Note: Gemini 3.1 Pro scores are recorded under Google DeepMind’s official High Thinking configuration. GPT OSS 120B scores reflect independent telemetry from Artificial Analysis using the AkashML and CoreWeave hosting clusters. While Gemini 3.1 Pro wins across all raw accuracy metrics, remember that Gemini runs on massive proprietary Google TPU clusters, whereas GPT OSS 120B runs on a single commodity 80GB GPU. Achieving a 23.5% score on Terminal-Bench and 38.2% on SWE-bench within a single 80GB GPU envelope represents an impressive feat of parameter efficiency.
5. Coding in Real Use: Practical Developer Scenarios
Benchmarks give a standardized snapshot, but how do these two models perform in everyday developer workflows? If you use AI coding editors like Cursor Pro or general coding assistants like GitHub Copilot, here is what you will experience in daily engineering practice.
1. Vibe Coding a Small App
When building a prototype from scratch—such as a React web application, a Tailwind CSS dashboard, or a FastAPI backend—both models perform admirably. GPT OSS 120B generates clean boilerplate, follows modern component structures, and creates interactive UI elements quickly. When hosted on fast inference engines like Cerebras (688 TPS) or Groq (292 TPS), it generates full files almost instantaneously. Gemini 3.1 Pro produces slightly more polished CSS and layout structures, but the difference on simple apps is small.
2. Debugging and Fixing Complex Errors
Debugging is where the models diverge. If you provide a stack trace involving multiple asynchronous function calls, GPT OSS 120B on low reasoning often suggests shallow syntax adjustments. It requires high reasoning effort to trace the actual state flow. In contrast, Gemini 3.1 Pro excels at analyzing subtle edge cases, identifying race conditions, and correctly diagnosing memory leaks across distributed components.
3. Working with a Large Codebase
This is Gemini’s biggest advantage. With its 1,000,000-token context window, you can pass an entire repository, including dozens of source files, documentation, and database schemas, directly into the prompt. Gemini maintains coherent understanding across all files. GPT OSS 120B has a 131,072-token window. While 131K tokens can hold approximately 100,000 lines of code, attempting to feed larger enterprise projects will cause context truncation. You must rely on retrieval-augmented generation (RAG) or semantic file search tools.
4. Autonomous Agent Tasks
In agentic coding setups—where the model writes code, executes tests in a terminal, inspects test failures, and writes git patches autonomously (as seen in tools like OpenHands or Devin)—Gemini 3.1 Pro is substantially more reliable. Its 68.5% Terminal-Bench completion rate means it rarely gets trapped in infinite execution loops. GPT OSS 120B (23.5% on high effort) requires human oversight to ensure it does not get confused by command syntax errors.
6. gpt-oss 120b pricing vs gemini 3 pro pricing: Hosted APIs, Self-Hosting, and the 200k Cliff
The cost difference between open-weight inference and closed proprietary APIs is dramatic. However, evaluating pricing requires separating Gemini’s tiered schedule from the decentralized hosting market of GPT OSS 120B.
Part A: gemini 3 pro pricing and the 200,000-Token Cliff
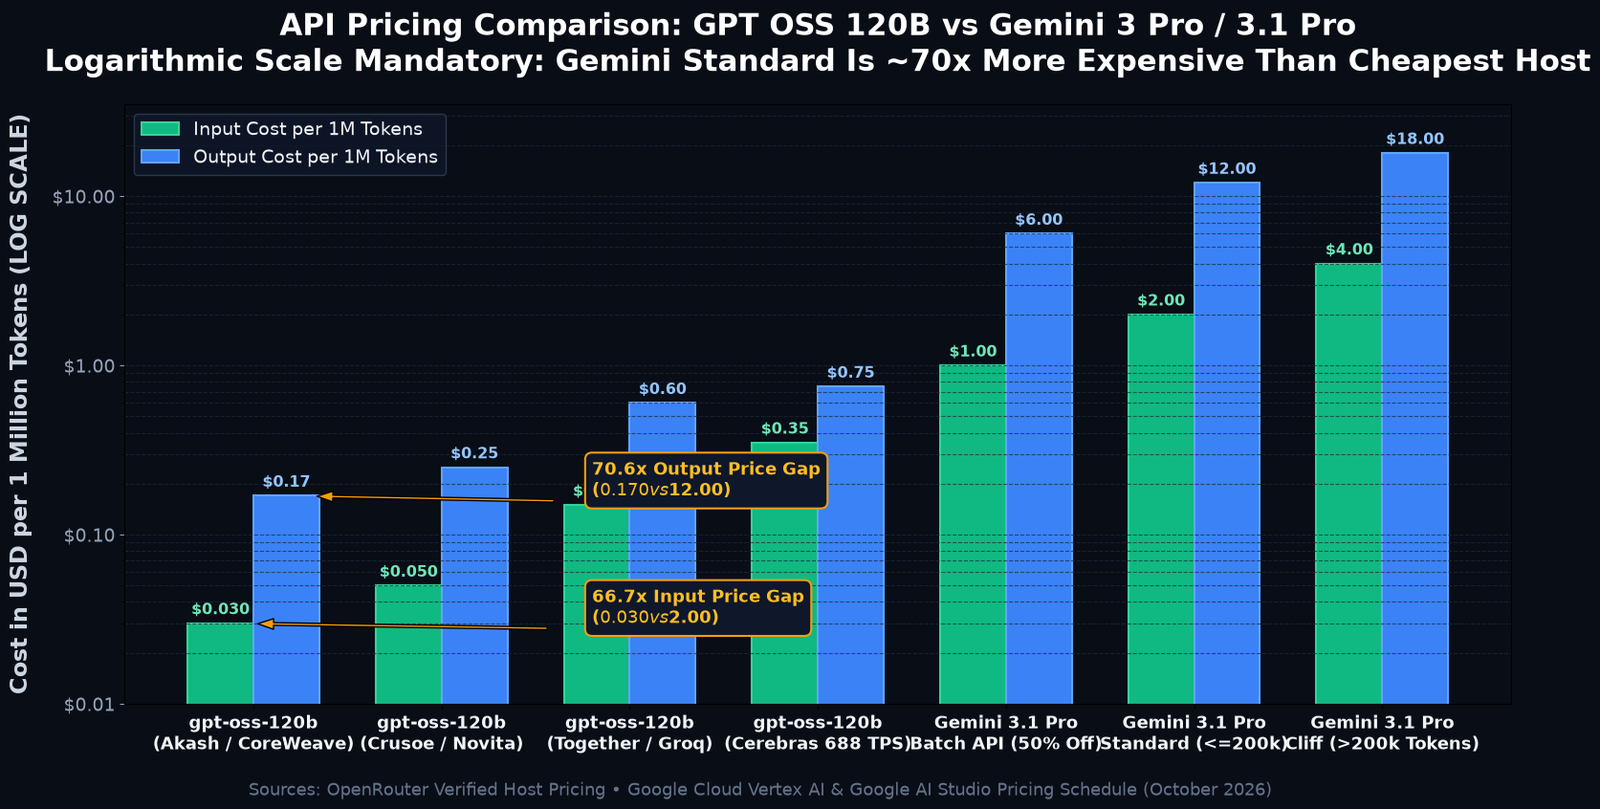
Google structures Gemini 3.1 Pro pricing into two tiers based on the total token length of your prompt:
- Standard Tier (Prompts ≤ 200,000 Tokens):
- Input Tokens: $2.00 per 1 million tokens
- Output Tokens (including thinking tokens): $12.00 per 1 million tokens
- The 200,000-Token Cliff (Prompts > 200,000 Tokens):
When your prompt exceeds 200,000 tokens, Google applies a steep pricing penalty. The input price doubles, and the output price increases by 50%:
- Input Tokens: $4.00 per 1 million tokens (2x increase)
- Output Tokens: $18.00 per 1 million tokens (1.5x increase)
- Discounts & Caching: Google provides a 50% discount on asynchronous Batch API requests ($1.00 in / $6.00 out) and charges $0.20 per 1M tokens for cached prompt reads.
Part B: gpt-oss 120b pricing (Hosted API vs Self-Hosting)
Because GPT OSS 120B has open weights, there is no single “official” price. Pricing depends entirely on where you run it:
- Budget Cloud Providers (AkashML, CoreWeave, DekaLLM):
- Input Tokens: $0.030 per 1 million tokens
- Output Tokens: $0.170 per 1 million tokens
- Price Ratio: At $0.030 input, it is 66.7 times cheaper than Gemini’s base input ($2.00 / $0.030). At $0.170 output, it is 70.6 times cheaper than Gemini’s base output ($12.00 / $0.170).
- Mid-Tier Managed Providers (Crusoe, NovitaAI, Mancer):
- Input Tokens: $0.050 / 1M • Output Tokens: $0.250 to $0.300 / 1M
- Enterprise & Specialized Hosts (Groq, Together AI, Amazon Bedrock):
- Input Tokens: $0.150 / 1M • Output Tokens: $0.600 / 1M
- Ultra-High Throughput (Cerebras):
- Input Tokens: $0.350 / 1M • Output Tokens: $0.750 / 1M (688 tokens/sec)
- Self-Hosting on Dedicated Hardware: Because the model fits on a single 80GB GPU with MXFP4 quantization, you can rent an NVIDIA H100 GPU on cloud marketplaces like RunPod or Lambda Labs for approximately $1.50 to $2.50 per hour. If you run tests for 30 hours in a month, your total server bill is $45 to $75 regardless of token volume. For complete air-gapping, purchasing a Mac Studio M2/M3 Ultra (128GB unified memory) costs around $4,000 upfront with zero ongoing token charges.
Assume an active developer workflow generating 80 million input tokens and 20 million output tokens over a 30-day period (100 million total tokens).
Option 1: GPT OSS 120B via AkashML (Cheapest Hosted API)
• Input: 80M × $0.030 / 1M = $2.40
• Output: 20M × $0.170 / 1M = $3.40
• Total Monthly Cost: $5.80
Option 2: GPT OSS 120B via Together AI / Groq (Mid-Tier Managed API)
• Input: 80M × $0.150 / 1M = $12.00
• Output: 20M × $0.600 / 1M = $12.00
• Total Monthly Cost: $24.00
Option 3: Gemini 3.1 Pro Standard API (Prompts ≤ 200k)
• Input: 80M × $2.00 / 1M = $160.00
• Output: 20M × $12.00 / 1M = $240.00
• Total Monthly Cost: $400.00
Option 4: Gemini 3.1 Pro Above the 200k Token Cliff
• Input: 80M × $4.00 / 1M = $320.00
• Output: 20M × $18.00 / 1M = $360.00
• Total Monthly Cost: $680.00
The Bottom Line: Gemini 3.1 Pro Standard costs 69.0x more than cheapest hosted GPT OSS 120B ($400.00 vs $5.80). Switching to GPT OSS 120B saves $394.20 per month—a 98.6% cost reduction. Above the 200k token cliff, Gemini costs 117.2x more ($680.00 vs $5.80).
7. Context Window and Long Codebases
How much code can each model actually hold, and what breaks when your project expands?
GPT OSS 120B provides a 131,072-token context window. In practice, 131K tokens accommodates roughly 100,000 words or approximately 4,000 to 5,000 lines of dense code along with conversation history. For small-to-medium microservices, individual component files, and targeted bug fixes, this is plenty of space. However, on large monorepos, you cannot pass the entire codebase at once. If your context exceeds 131K tokens, your inference engine will return an error or silently truncate the oldest messages.
Gemini 3.1 Pro provides a massive 1,000,000-token window (with select enterprise tiers reaching 2,000,000 tokens). A 1-million-token window can swallow entire software packages, complete documentation wikis, dozens of third-party libraries, and extensive database schemas simultaneously. In benchmark tests on long-context retrieval (such as needle-in-a-haystack code queries), Gemini retrieves functions buried deep in 500,000-token prompts with near 100% accuracy.
The Catch with Gemini’s Long Context: As detailed in Section 6, the moment your prompt crosses 200,000 tokens, you trigger Google’s pricing cliff. Your input cost doubles from $2.00 to $4.00 per million, and output jumps to $18.00. Using Gemini’s million-token context casually can produce massive monthly cloud bills. To manage this, developers must leverage Google’s context caching feature, which stores prompt tokens at $0.20 per million after an initial write.
8. Privacy and Control: open weight vs closed model
Beyond benchmark scores and token costs, the choice between open weight vs closed model architectures defines your operational security and data sovereignty.
Data Privacy & Compliance
With GPT OSS 120B, you own the weights. If you deploy the model on a local workstation or inside a dedicated, air-gapped Virtual Private Cloud (VPC), your proprietary source code never leaves your network perimeter. No logs are saved to external cloud servers, and no third party can inspect your proprietary algorithms. For developers working under strict HIPAA, GDPR, financial compliance rules, or strict non-disclosure agreements, open weights provide complete peace of mind.
With Gemini 3.1 Pro, your code is dispatched to Google Cloud data centers. While Google’s enterprise terms guarantee that API data is not used to train future public models, many enterprise security teams maintain zero-trust policies that strictly forbid transmitting core intellectual property to third-party endpoints.
Control, Fine-Tuning, and Refusals
Open weights allow you to fine-tune the model on your team’s specific coding guidelines, proprietary libraries, and internal APIs. Furthermore, GPT OSS 120B does not suffer from aggressive corporate content guardrails that refuse benign developer requests. In contrast, Gemini’s closed cloud API includes safety filters that can occasionally trigger false-positive refusals when analyzing cybersecurity tools, penetration testing scripts, reverse-engineering utilities, or raw vulnerability reports.
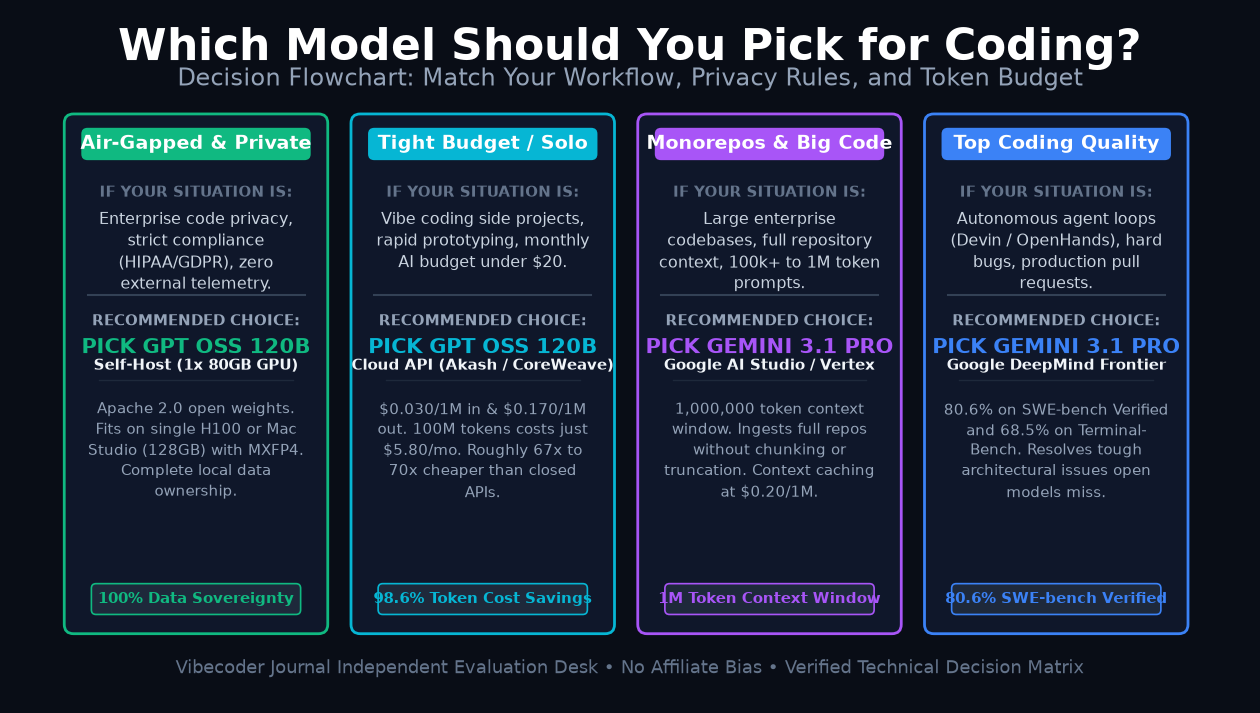
9. Who Should Pick Which Model?
Different development workflows demand different strengths. Here is who should choose each model:
- Solo Vibe Coders & Indie Hackers: Pick GPT OSS 120B via hosted API. When building and testing new product ideas, you iterate through hundreds of prompts daily. Using hosted GPT OSS 120B on AkashML or CoreWeave keeps your monthly AI bill under $10, letting you experiment aggressively without watching a token meter.
- Startups on a Tight Runway: Pick GPT OSS 120B. If your software product relies on high-volume background code processing or automated syntax evaluation, saving 98.6% on token inference costs can extend your operating runway by months.
- Enterprises with Sensitive or Proprietary Code: Pick GPT OSS 120B (Self-Hosted). Deploying on private 80GB GPUs gives your engineering team full frontier reasoning while maintaining 100% air-gapped data compliance.
- Teams Requiring Top Coding Quality & Autonomous Agents: Pick Gemini 3.1 Pro. If you are building autonomous coding agents that write, execute, and debug multi-file patches on production repositories, Gemini’s 80.6% SWE-bench score and superior terminal triage prevent hallucinated code and broken builds.
- Developers Refactoring Massive Monorepos: Pick Gemini 3.1 Pro. If you need the model to understand your entire 500,000-token repository architecture simultaneously, Gemini’s 1-million-token window is the only option that will not truncate your files.
10. Final Verdict Table
There is no single “overall winner” between these two models. Each dominates in specific development environments:
| Evaluation Dimension | Winner | Deciding Factor |
|---|---|---|
| Raw Coding & Bug Fixing Quality | Gemini 3.1 Pro | 80.6% on SWE-bench Verified vs 38.2%; superior terminal agent triage (68.5% vs 23.5%). |
| Token Price & Operating Cost | GPT OSS 120B | $0.030/1M input vs $2.00/1M on Gemini (~67x cheaper); saves 98.6% on standard monthly workloads. |
| Data Privacy & Ownership | GPT OSS 120B | Apache 2.0 open weights run locally or in private VPC; zero data transmitted to Google. |
| Large Repository Context | Gemini 3.1 Pro | 1,000,000 tokens ingests entire codebases; GPT OSS 120B is bounded at 131,072 tokens. |
| Peak Generation Speed (TPS) | GPT OSS 120B | Reaches 688 tokens/sec on Cerebras ASIC inference; Gemini averages 35–50 tokens/sec. |
| Self-Hosting & Air-Gapped Use | GPT OSS 120B | Fits onto a single 80GB GPU via MXFP4 quantization; Gemini cannot be self-hosted. |
11. Frequently Asked Questions
Yes, the weights are free under the Apache 2.0 license. You can download and run them without licensing fees. However, running the model requires hardware compute: either your own 80GB GPU or pay-as-you-go cloud hosting, which starts at $0.030 per million input tokens.
Yes, provided you have sufficient memory. Thanks to MXFP4 quantization, the model fits into 80GB of VRAM. A high-end workstation with an NVIDIA H100 GPU or an Apple Mac Studio with 128GB of unified memory can run the model locally using Ollama or vLLM.
Yes, in terms of accuracy and complex reasoning. Gemini 3.1 Pro scores 80.6% on SWE-bench Verified compared to 38.2% for GPT OSS 120B on high reasoning. It resolves tough bugs, multi-file conflicts, and autonomous agent tasks with noticeably fewer errors and hallucinations.
GPT OSS 120B is substantially cheaper. On budget cloud hosts like AkashML and CoreWeave, input costs $0.030 per million tokens and output costs $0.170. Gemini 3.1 Pro charges $2.00 input and $12.00 output, making Gemini roughly 67 to 70 times more expensive.
Gemini has a far larger context window. Gemini 3.1 Pro handles 1,000,000 tokens (up to 2,000,000 on select tiers), allowing it to hold entire repositories. GPT OSS 120B supports 131,072 tokens, which holds approximately 100,000 words or 5,000 lines of code.
Google officially decommissioned and archived Gemini 3 Pro (gemini-3-pro-preview) in late September 2026. Requests to the old endpoint return deprecation errors. Google replaced it with Gemini 3.1 Pro Preview, which now serves as the active frontier reasoning checkpoint in Google AI Studio.

Keep exploring