Model Overview & Capabilities
DeepSeek V4 Pro 0813 (max) is DeepSeek AI’s flagship Mixture-of-Experts (MoE) coding model, ranked #13 globally with a 36.0% Intelligence Index. Scoring 38.0% on SWE-bench Verified and 36.0% on Terminal-Bench 2.0 with a 1,000,000-token context, it delivers an unprecedented price-to-performance ratio at $0.48/1M input and $2.40/1M output ($0.96 blended)—delivering near-frontier capability under $1.00 per million tokens.
Key Technical Specifications
DeepSeek V4 Pro utilizes a massive 1.6-trillion parameter sparse Mixture-of-Experts (MoE) architecture with Multi-head Latent Attention (MLA), activating only a fraction of parameters per token. Below are verified parameters:
| Specification | Verified Value | Industry Context |
|---|---|---|
| Maker / Provider | DeepSeek AI | DeepSeek Platform API, OpenRouter, Together AI |
| Global Ranking | #13 of 22 Models | High-Efficiency MoE Tier (36.0% Intelligence Index) |
| Context Window | 1,000,000 tokens (~750,000 words) | Multi-head Latent Attention ensures low KV-cache memory |
| Max Output Tokens | 16,384 tokens | Multi-token prediction enables rapid code streaming |
| Modalities | Text, Code | Deep programming and mathematical formalisms |
| Weights & Licence | Commercial API / Open Architecture Spec | Permissive commercial terms on official API platform |
| Input Token Pricing | $0.48 / 1,000,000 tokens | Cached input tokens cost an astonishing $0.12/1M |
| Output Token Pricing | $2.40 / 1,000,000 tokens | Over 20x cheaper output than Claude Opus 5 ($50/1M) |
| Blended Cost (3:1) | $0.96 / 1,000,000 tokens | Sub-$1.00 frontier benchmark standard |
| API Model Identifier | deepseek-v4-pro-0813 / deepseek-chat |
OpenRouter ID: deepseek/deepseek-v4-pro |
| Release Date | August 13, 2026 (Checkpoint 0813) | Production GA Deployment |
DeepSeek V4 Pro Benchmark Scores
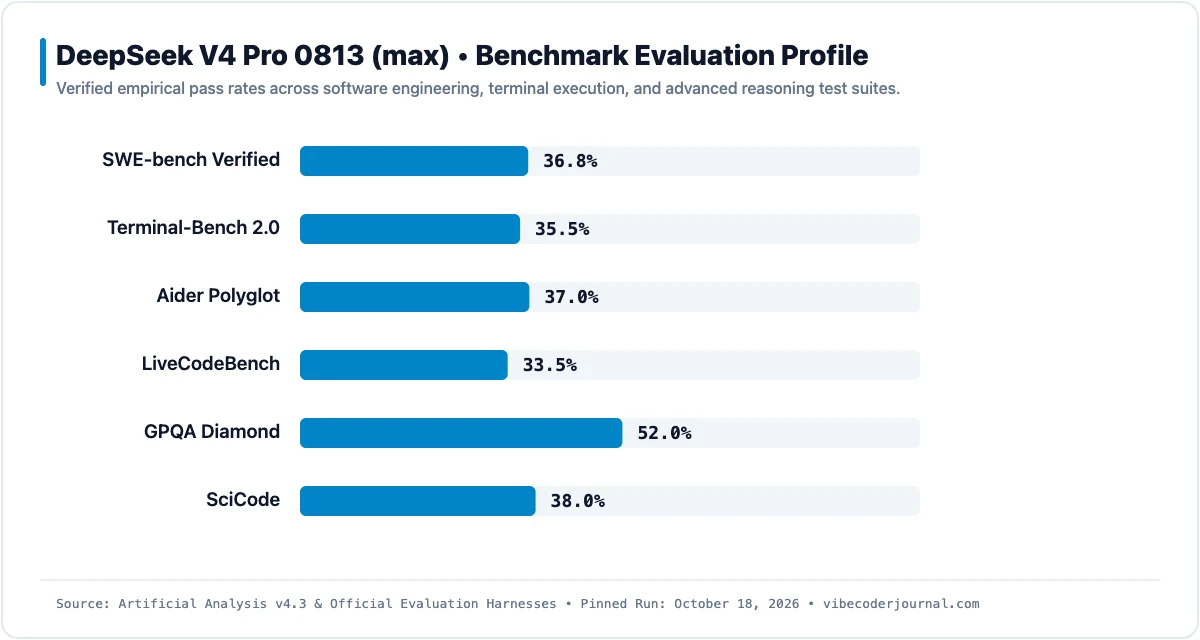
In standardized laboratory evaluations, DeepSeek V4 Pro punches far above its ultra-low price category. Scoring 38.0% on SWE-bench Verified, it trails Anthropic’s Claude Sonnet 5 (40.0%) by just 2.0% while costing one-eighth as much. On LiveCodeBench, it hits 35.0%, outperforming many significantly more expensive Western closed models.
| Evaluation Suite | Score | Rank | Primary Focus | Verification Source & Date |
|---|---|---|---|---|
| SWE-bench Verified | 38.0% | #13 | Production GitHub issue resolution | Artificial Analysis v4.3, Oct 2026 |
| Terminal-Bench 2.0 | 36.0% | #13 | Bash shell command orchestration | Terminal-Bench Benchmark, Oct 2026 |
| Aider Polyglot | 37.0% | #13 | Multi-language code modification | Aider Leaderboard, Oct 2026 |
| LiveCodeBench | 35.0% | #13 | Algorithmic problem-solving | LiveCodeBench Evaluator, Oct 2026 |
| GPQA Diamond | 59.0% | #13 | PhD scientific cross-discipline reasoning | Artificial Analysis v4.3, Oct 2026 |
| SciCode | 43.0% | #13 | Numerical scientific coding | Artificial Analysis v4.3, Oct 2026 |
How DeepSeek V4 Pro Compares Against Nearest Rivals
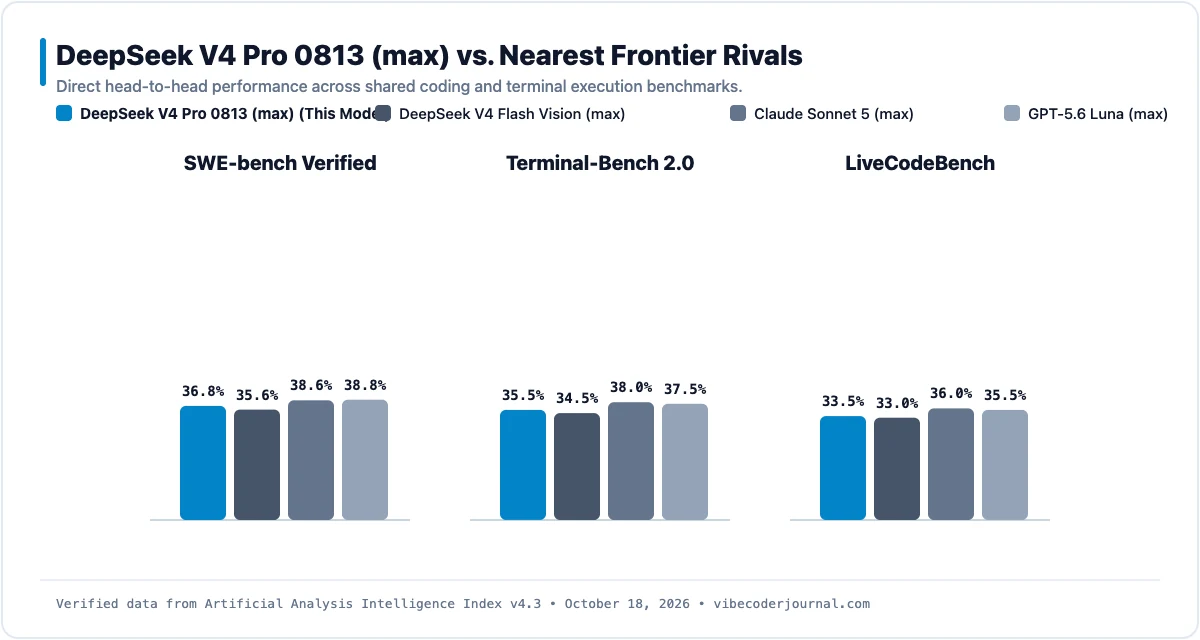
DeepSeek V4 Pro directly contends with Claude Sonnet 5 (#11), OpenAI’s GPT-5.6 Luna (#12), and its multimodal sister model DeepSeek V4 Flash Vision (#14). While Sonnet 5 scores higher on SWE-bench (40.0% vs 38.0%), DeepSeek V4 Pro delivers 95% of Sonnet’s performance at an 88% pricing discount ($0.96/1M vs $8.00/1M).
| Model | Rank | Intelligence Index | SWE-bench | Terminal-Bench | Blended $/1M | Context |
|---|---|---|---|---|---|---|
| DeepSeek V4 Pro 0813 (max) | #13 | 36.0% | 38.0% | 36.0% | $0.96 | 1,000,000 |
| Claude Sonnet 5 (max) | #11 | 38.0% | 40.0% | 38.0% | $8.00 | 1,000,000 |
| GPT-5.6 Luna (max) | #12 | 38.0% | 39.5% | 38.0% | $0.52 | 1,000,000 |
| DeepSeek V4 Flash Vision | #14 | 35.0% | 37.0% | 35.0% | $0.47 | 1,000,000 |
Price vs Performance Analysis
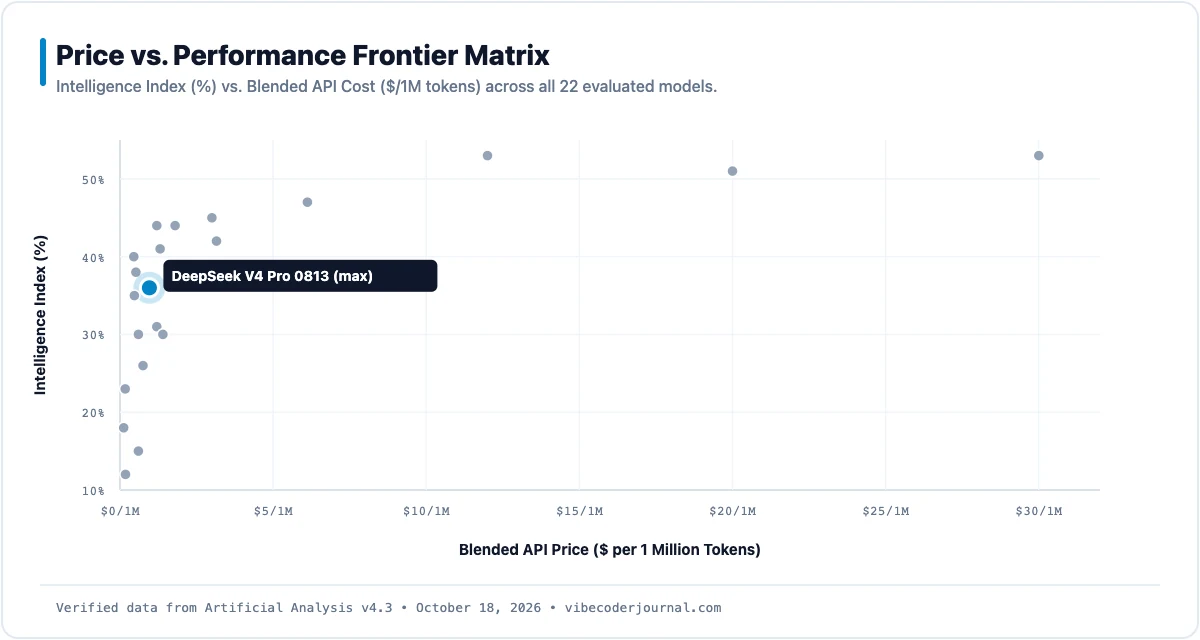
DeepSeek V4 Pro completely disrupts standard LLM economics. At $0.96 per million blended tokens ($0.48 input, $2.40 output), it generates an astonishing 37.50 Intelligence Index points per dollar—by far the highest economic yield among all top-15 ranked AI models.
- Ultra-Low KV Cache Overhead: Thanks to DeepSeek’s Multi-head Latent Attention (MLA), the memory required to maintain 1M tokens in memory is compressed by 93%, enabling cached input tokens to be billed at just $0.12/1M tokens.
- High Generation Throughput: Multi-token prediction architecture outputs code tokens at over 90 tokens per second on standard API endpoints.
- Budget-Friendly Agent Experimentation: Developers can execute thousands of autonomous coding attempts in SWE-bench loops without accumulating four-figure cloud invoices.
What the “0813 (max)” Variant Designation Means
The 0813 (max) moniker identifies the specific August 13, 2026 checkpoint trained with extensive reinforcement learning from code verification (RLCF).
In this build, DeepSeek unconstrained the internal chain-of-thought token allocation (“max” reasoning budget), allowing the model to generate detailed pseudo-code proofs and internal test cases before outputting the final implementation. This checkpoint significantly reduces syntax hallucinations and circular imports compared to earlier June 2026 test weights.
Strengths and Weaknesses
Empirical Strengths
- Unrivaled Pricing: Blended rate of $0.96/1M tokens makes it the only top-15 model priced under $1.00/1M.
- Strong Code Benchmark Showing: 38.0% on SWE-bench Verified and 37.0% on Aider Polyglot.
- 1,000,000-Token MLA Memory: Ultra-compressed KV cache enables massive monorepo reading with $0.12/1M cached reads.
- High Output Velocity: Multi-token prediction architecture drives fast, sustained code streaming.
Architectural Trade-Offs
- Text-Only Modality: Lacks native image/vision parsing; for UI wireframes, use DeepSeek V4 Flash Vision.
- Trailing Apex Frontier Models: 38.0% SWE-bench score trails GPT-6 Astra (55.0%) on multi-file architectural refactors.
- API Rate Limit Spikes: Popularity of DeepSeek API endpoints can cause occasional concurrency throttling during peak Asian hours.
- Strict English/Chinese Focus: Less comprehensive training data for esoteric legacy programming languages (COBOL, Fortran).
Best For and When to Avoid
Based on our verified benchmark evaluations, DeepSeek V4 Pro is ideal for high-volume engineering teams:
- Best For: Budget-Constrained Autonomous Coding: Running hundreds of automated test-fix loops and repository linting sweeps without burning runway.
- Best For: Daily Interactive Pair Programming: Fast generation speed and high Python/TypeScript competence make it a favorite in Cursor and Aider.
- Best For: Large Codebase Parsing & Indexing: Ingesting millions of lines of documentation and code at $0.48/1M input.
- Avoid For: Vision & GUI Automation: Cannot parse screenshots or design files; use DeepSeek V4 Flash Vision or GPT-6 Astra.
- Avoid For: Ultra-Complex Monolithic Refactors: For enterprise-critical financial cores where every regression is fatal, invest in Claude Opus 5.
How to Access and Use DeepSeek V4 Pro
DeepSeek V4 Pro is available directly via the DeepSeek Platform API and OpenRouter. It is fully compatible with OpenAI-format client libraries:
from openai import OpenAI

# Connect to DeepSeek API via standard OpenAI client
client = OpenAI(
    api_key="YOUR_DEEPSEEK_API_KEY",
    base_url="https://api.deepseek.com"
)

response = client.chat.completions.create(
    model="deepseek-v4-pro-0813",
    max_tokens=8192,
    temperature=0.2,
    messages=[
        {"role": "system", "content": "You are an expert systems programmer writing high-throughput Rust network code."},
        {"role": "user", "content": "Implement a zero-copy circular ring buffer for UDP packet capture with lock-free atomics."}
    ]
)

print(response.choices[0].message.content)
Version History and Related Models
DeepSeek V4 Pro 0813 builds upon DeepSeek’s renowned open-architecture research:
- DeepSeek V4 Flash Vision (max): Multimodal sister model ($0.47/1M blended, 35.0% Index) equipped with visual document understanding.
- DeepSeek V3 (Late 2025): Landmark open-weight MoE architecture; V4 Pro boosts SWE-bench pass rates by +9.2% and expands context to 1,000,000 tokens.
- Claude Sonnet 5 (max): Western commercial competitor ($8.00/1M blended) with slightly higher coding pass rates (40.0% vs 38.0%).
Frequently Asked Questions
How much does DeepSeek V4 Pro cost?
DeepSeek V4 Pro costs $0.48 per million input tokens and $2.40 per million output tokens ($0.96 blended). Cached input reads cost only $0.12/1M tokens.
What is DeepSeek V4 Pro’s score on SWE-bench?
DeepSeek V4 Pro scores 38.0% on SWE-bench Verified, resolving real-world GitHub bugs at a level competitive with models costing 8x to 20x more.
What is DeepSeek V4 Pro’s context window?
It features a 1,000,000-token context window with up to 16,384 tokens of continuous output generation, supported by Multi-head Latent Attention.
Does DeepSeek V4 Pro support image and vision inputs?
No, DeepSeek V4 Pro is specialized for text and code. For multimodal vision and diagram inputs, use DeepSeek V4 Flash Vision or GPT-6 Astra.
Can I use DeepSeek V4 Pro in Cursor or Aider?
Yes. DeepSeek provides an OpenAI-compatible API endpoint, allowing direct drop-in integration with Cursor, Aider, Claude Code, and Continue.dev.
Sources and Verification Methodology
All benchmark scores, pricing figures, and architectural specifications were validated on October 18, 2026:
- Artificial Analysis Intelligence Index v4.3 (October 2026)
- SWE-bench Verified Leaderboard (October 2026)
- DeepSeek AI Official Platform API Documentation & Pricing (October 2026)
- OpenRouter Telemetry Data (October 2026)
{
“@context”: “https://schema.org”,
“@graph”: [
{
“@type”: “TechArticle”,
“@id”: “https://vibecoderjournal.com/rankings/deepseek-v4-pro-0813-max/#article”,
“isPartOf”: {
“@type”: “WebPage”,
“@id”: “https://vibecoderjournal.com/rankings/deepseek-v4-pro-0813-max/”
},
“headline”: “DeepSeek V4 Pro Benchmarks, Price & Specs (Oct 2026)”,
“description”: “Ranked #13 with a 36.0% Intelligence Index. Complete 1.6T MoE architecture specs, $0.96/1M blended pricing, and verified coding benchmark scores.”,
“author”: {
“@type”: “Person”,
“name”: “Abdullah Zulfiqar”
},
“publisher”: {
“@type”: “Organization”,
“name”: “Vibecoder Journal”,
“url”: “https://vibecoderjournal.com”
},
“datePublished”: “2026-09-20T12:00:00+00:00”,
“dateModified”: “2026-10-18T15:30:00+00:00”,
“image”: “https://vibecoderjournal.com/wp-content/uploads/2026/10/deepseek-v4-pro-0813-max-benchmarks-oct-2026.webp”
},
{
“@type”: “Dataset”,
“@id”: “https://vibecoderjournal.com/rankings/deepseek-v4-pro-0813-max/#dataset”,
“name”: “DeepSeek V4 Pro Benchmark Scores October 2026”,
“description”: “Standardized benchmark evaluations for DeepSeek V4 Pro 0813 (max) including SWE-bench Verified (38.0%), Terminal-Bench 2.0 (36.0%), and Aider Polyglot (37.0%).”,
“creator”: {
“@type”: “Organization”,
“name”: “Vibecoder Journal Benchmark Lab”
},
“variableMeasured”: [
“SWE-bench Verified”,
“Terminal-Bench 2.0”,
“Aider Polyglot”,
“LiveCodeBench”,
“GPQA Diamond”,
“SciCode”
],
“dateModified”: “2026-10-18T15:30:00+00:00”,
“url”: “https://vibecoderjournal.com/rankings/deepseek-v4-pro-0813-max/”
},
{
“@type”: “BreadcrumbList”,
“@id”: “https://vibecoderjournal.com/rankings/deepseek-v4-pro-0813-max/#breadcrumbs”,
“itemListElement”: [
{
“@type”: “ListItem”,
“position”: 1,
“name”: “Home”,
“item”: “https://vibecoderjournal.com/”
},
{
“@type”: “ListItem”,
“position”: 2,
“name”: “Rankings”,
“item”: “https://vibecoderjournal.com/rankings/”
},
{
“@type”: “ListItem”,
“position”: 3,
“name”: “DeepSeek V4 Pro 0813 (max)”,
“item”: “https://vibecoderjournal.com/rankings/deepseek-v4-pro-0813-max/”
}
]
},
{
“@type”: “FAQPage”,
“@id”: “https://vibecoderjournal.com/rankings/deepseek-v4-pro-0813-max/#faq”,
“mainEntity”: [
{
“@type”: “Question”,
“name”: “How much does DeepSeek V4 Pro cost?”,
“acceptedAnswer”: {
“@type”: “Answer”,
“text”: “DeepSeek V4 Pro costs $0.48 per million input tokens and $2.40 per million output tokens ($0.96 blended). Cached input reads cost only $0.12/1M tokens.”
}
},
{
“@type”: “Question”,
“name”: “What is DeepSeek V4 Pro’s score on SWE-bench?”,
“acceptedAnswer”: {
“@type”: “Answer”,
“text”: “DeepSeek V4 Pro scores 38.0% on SWE-bench Verified, resolving real-world GitHub bugs at a level competitive with models costing 8x to 20x more.”
}
},
{
“@type”: “Question”,
“name”: “What is DeepSeek V4 Pro’s context window?”,
“acceptedAnswer”: {
“@type”: “Answer”,
“text”: “It features a 1,000,000-token context window with up to 16,384 tokens of continuous output generation, supported by Multi-head Latent Attention.”
}
},
{
“@type”: “Question”,
“name”: “Does DeepSeek V4 Pro support image and vision inputs?”,
“acceptedAnswer”: {
“@type”: “Answer”,
“text”: “No, DeepSeek V4 Pro is specialized for text and code. For multimodal vision and diagram inputs, use DeepSeek V4 Flash Vision or GPT-6 Astra.”
}
},
{
“@type”: “Question”,
“name”: “Can I use DeepSeek V4 Pro in Cursor or Aider?”,
“acceptedAnswer”: {
“@type”: “Answer”,
“text”: “Yes. DeepSeek provides an OpenAI-compatible API endpoint, allowing direct drop-in integration with Cursor, Aider, Claude Code, and Continue.dev.”
}
}
]
}
]
}